
- Home
- Informatica Certifications
- PR000041 PowerCenter Data Integration 9.x:Developer Specialist Dumps
Pass Informatica PR000041 Exam in First Attempt Guaranteed!
Get 100% Latest Exam Questions, Accurate & Verified Answers to Pass the Actual Exam!
30 Days Free Updates, Instant Download!


PR000041 Premium File
- Premium File 70 Questions & Answers. Last Update: Nov 10, 2026
Whats Included:
- Latest Questions
- 100% Accurate Answers
- Fast Exam Updates
Last Week Results!
 83% students found the test questions almost same
PR000041: PowerCenter 9.x Developer Specialist Exam
PR000041 is the legacy PowerCenter Data Integration 9.x Developer Specialist exam. Informatica’s archived certification description says the assessment measured the ability to build basic and advanced mappings, use PowerCenter Designer, Workflow Manager, and Workflow Monitor, work with transformations, and build and run workflows as part of a database development team. Those objectives capture a classic ETL developer role, but the 9.x version places the exam in an older PowerCenter generation.
Current candidates should confirm active options through Informatica certifications, where newer PowerCenter and cloud credentials supersede the old 9.x context. For practitioners maintaining established PowerCenter estates, however, the underlying skills remain useful: understand source and target structures, transform data accurately, manage lookup and aggregation behavior, design reusable logic, build workflows, diagnose sessions, and move integrations safely through the development lifecycle.
A mapping is a data-processing design, not just a sequence of icons
PowerCenter mappings describe how source records become target records. Each transformation should have a clear purpose: filter rows, derive values, join datasets, look up reference information, aggregate measures, route records, generate keys, or apply another defined rule. Candidates should be able to explain data shape before and after each step and understand what happens when an input is null, duplicated, late, malformed, or missing.
Visual tools can make a pipeline look intuitive while hiding complexity. The developer still needs to reason about row counts, keys, data types, precision, ordering, and error behavior. A diagram is only correct if the resulting data is correct. For preparation, take a small dataset and calculate the expected output manually before building the mapping; then use discrepancies to understand transformation behavior.
Source analysis prevents integration logic from encoding false assumptions
A mapping often fails conceptually long before it fails technically because the developer misunderstood the source. Profile key fields, identify optional values, examine duplicate rates, confirm date and numeric formats, and understand the meaning of status codes. Data types alone do not describe business semantics. Two columns named “customer_id” may not identify the same grain or lifecycle in two systems.
The discipline of data profiling in ETL is especially useful here. It turns assumptions into evidence and guides transformation design. When developers skip profiling, they often compensate later with increasingly complex expressions and exception logic. Strong source understanding usually produces simpler, more defensible mappings.
Transformations should be chosen for semantics and execution behavior
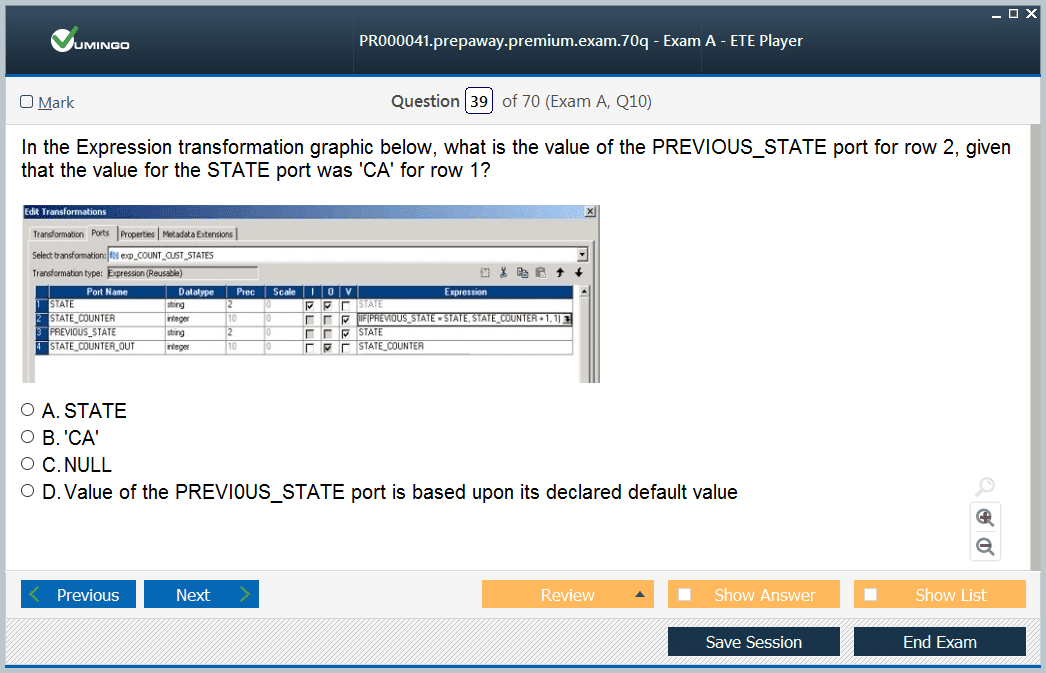
PowerCenter provides transformations for expression logic, filtering, sorting, aggregation, lookups, joining, routing, ranking, sequence generation, and other tasks. Knowing a transformation name is not enough. The developer must understand input requirements, state, cache behavior where relevant, row-level consequences, and whether the transformation can change the number or order of records.
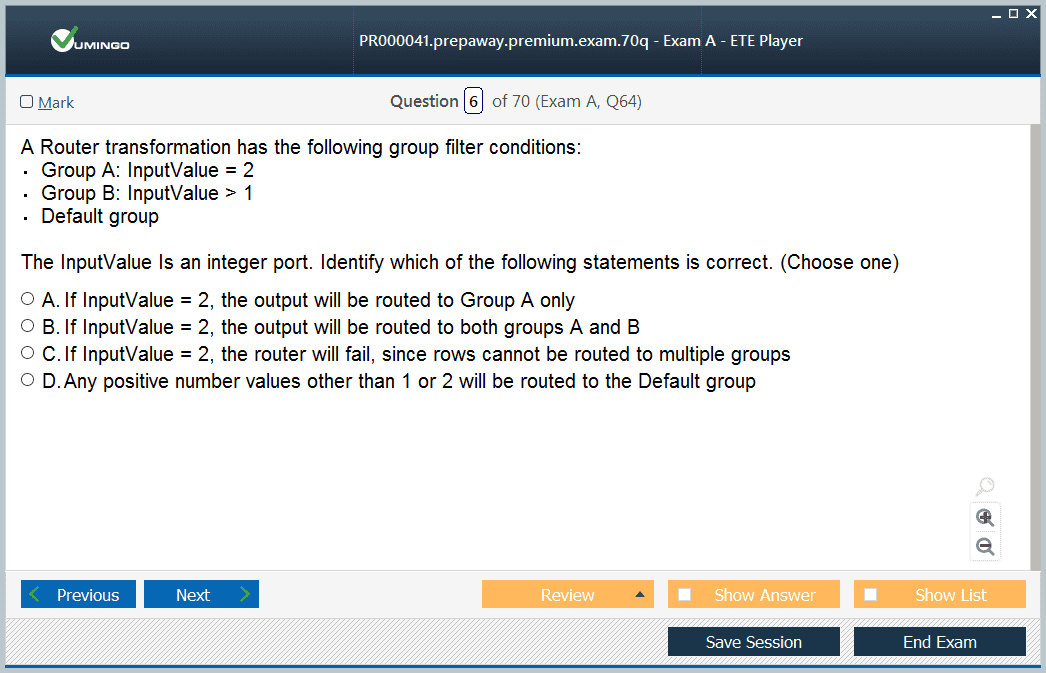
Compare transformations that can solve similar-looking problems. A lookup and a join both combine information, but they make different assumptions and have different operational characteristics. A filter and a router both direct rows, but a router can express multiple groups. The exam-era developer was expected to select tools intentionally, which remains a useful engineering habit in modern integration platforms.
Lookup and reference-data logic needs explicit handling for misses and duplicates
Reference data is often used to translate codes, enrich records, or validate relationships. A lookup design should define what constitutes a match, what happens when no match exists, and how multiple potential matches are handled. Assuming reference tables are always unique can produce nondeterministic or incorrect results when real data violates that assumption.
Developers should also understand the cost of repeated reference access and the role of caching or persistence where supported. Performance decisions must preserve correctness. A faster lookup that serves stale values may be unacceptable for some processes but harmless for others. Study each optimization together with its data-freshness and memory tradeoffs rather than treating performance switches as universally beneficial.
Aggregation and sorting can change both meaning and resource demand
Aggregations compress many input rows into fewer output groups, which makes keys and grouping definitions critical. A missing grouping field can merge unrelated business entities; an extra grouping field can fragment measures and change totals. Sorting can be necessary for some operations and can also consume substantial memory or temporary storage on large data sets.
Practice with row-count expectations. Before executing a mapping, estimate how many rows should enter and leave major transformations. If a supposed one-to-one enrichment doubles the record count, investigate the join or lookup relationship. If an aggregation produces more groups than expected, recheck the business grain. These simple controls catch errors that technically successful sessions may not flag.
Workflows turn mapping logic into scheduled, recoverable operations
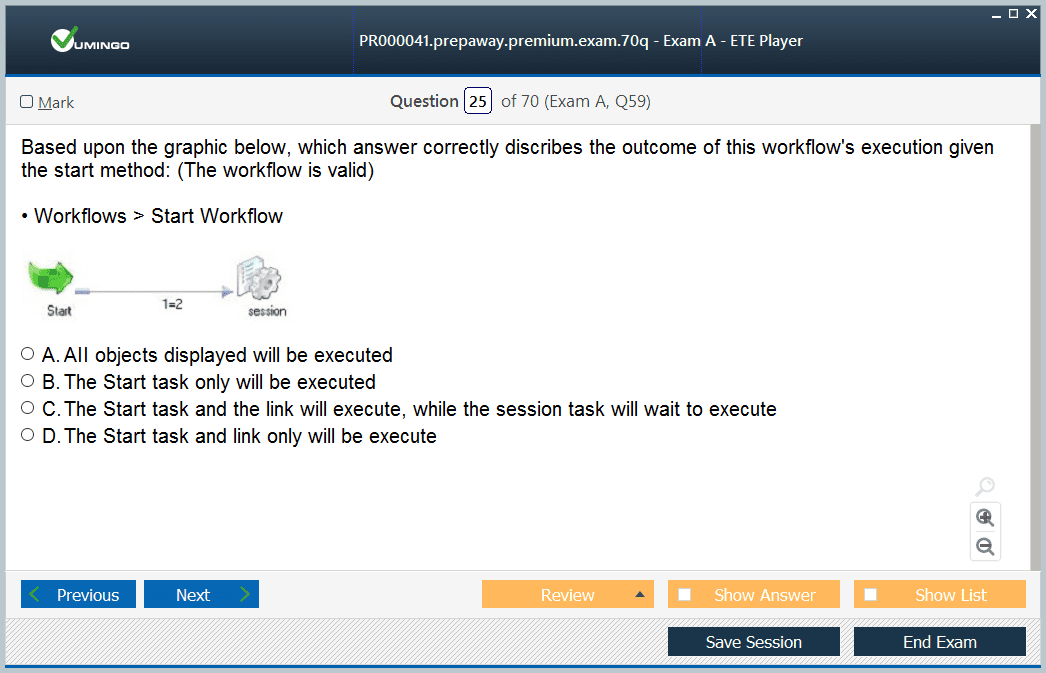
A mapping defines transformation logic; a workflow coordinates when and how that logic runs. Sessions, dependencies, conditions, variables, parameters, and task sequencing determine operational behavior. Candidates should understand how a data pipeline reacts to failure and whether downstream work should stop, continue, retry, or follow an alternate path.
Workflow design should reflect business dependencies. Loading a fact table before required dimensions or publishing a report before validation finishes creates errors even if individual sessions succeed. Think in terms of gates: what must be true before the next task starts, what evidence confirms success, and what recovery path avoids duplicating data. This makes workflows easier to operate and troubleshoot.
Incremental loading requires a reliable definition of what changed
Full reloads are simple conceptually but can be expensive or disruptive. Incremental patterns identify new or changed records using timestamps, sequence values, source flags, change-data mechanisms, comparison tables, or other evidence. The design must account for late-arriving updates, deletes, replay, and clock or transaction-boundary issues. A weak watermark strategy can silently miss records.
Study incremental loading as a state-management problem. Record the last safe point, process changes after that point, verify completion, then advance state. If execution fails midway, recovery should not create gaps or duplicates. The broader architecture of data warehouses is useful context because integration jobs often exist to maintain historical analytical structures rather than simply copy tables.
Workflow Monitor is a reasoning tool for performance and failure analysis
Monitoring should answer where a pipeline slowed or failed, not merely confirm that an error occurred. Developers need to read session statistics, transformation counts, source and target throughput, error messages, and task status. If one stage reads quickly but writes slowly, the investigation differs from a source query that takes most of the runtime.
Use evidence to isolate bottlenecks. Database plans, network transfer, transformation complexity, cache behavior, target constraints, and competing workloads can all affect performance. Changing multiple settings at once makes diagnosis harder. Establish a baseline, modify one meaningful factor, measure again, and keep correctness checks in place so a faster run does not hide lost or duplicated data.
Legacy objectives remain useful when converted into present-day integration skills
PR000041 should not be treated as proof that a 9.x exam is currently offered. It is best used as a historical competency map for PowerCenter developers. Current certification candidates should obtain the live Informatica exam outline and compare it with these older objectives, retaining transferable skills while replacing obsolete tool procedures and product-version assumptions.
A practical capstone is to design an ETL flow from a messy operational source into an analytical target. Profile the data, define the grain, apply transformations, enrich from reference data, handle rejects, build an incremental strategy, orchestrate a workflow, and specify monitoring and recovery. That exercise demonstrates the engineering judgment behind PR000041 and remains relevant even as the product platform evolves.
Error handling should preserve evidence and support safe restart
Production integrations encounter rejected rows, unavailable systems, duplicate files, late data, constraint violations, and partial completion. A developer should decide which errors are fatal, which records can be quarantined, which conditions should trigger retry, and how operations will know what happened. Simply discarding bad rows to make a session succeed damages trust because the pipeline no longer explains the difference between source and target.
Restart design is equally important. If a workflow fails after loading half of a target, rerunning from the beginning can create duplicates unless the process is idempotent or recovery state is controlled. Developers can use transaction boundaries, staging tables, batch identifiers, checkpoints, or other patterns to make retries predictable. The correct approach depends on target behavior and business tolerance for partial data.
Operational metadata should make exceptions actionable. Capture the source record or stable identifier, rejection reason, processing time, and enough context for a steward or developer to investigate. Separate business-data defects from technical failures: an invalid postal code may require data correction, while a lost database connection requires platform recovery. Designing that distinction into the workflow reduces troubleshooting time and keeps data-quality responsibilities clear.
Parameterization can make mappings reusable across dates, files, environments, and business units, but it also creates another source of hidden behavior. Developers should know which values are fixed in the mapping, supplied by a workflow, inherited from a parameter file, or resolved from the runtime environment. When a process behaves differently between test and production, configuration provenance should be checked before changing transformation logic.
Version control and peer review strengthen this discipline. Even when a repository manages objects, teams should still establish a release convention that identifies who changed a mapping, why it changed, which requirement or defect it addresses, and what evidence shows that results remain correct. Integration code deserves the same traceability as application code because an unnoticed transformation change can alter thousands or millions of downstream records without producing a technical error.
Good developers also validate totals and business invariants after a load. Row counts alone are insufficient when one input record can legitimately create several target records. Reconcile monetary totals, key populations, date ranges, and other domain-specific expectations so a technically successful workflow cannot silently publish an incorrect dataset.
Why customers love us?
What do our customers say?
The resources provided for the Informatica certification exam were exceptional. The exam dumps and video courses offered clear and concise explanations of each topic. I felt thoroughly prepared for the PR000041 test and passed with ease.
Studying for the Informatica certification exam was a breeze with the comprehensive materials from this site. The detailed study guides and accurate exam dumps helped me understand every concept. I aced the PR000041 exam on my first try!
I was impressed with the quality of the PR000041 preparation materials for the Informatica certification exam. The video courses were engaging, and the study guides covered all the essential topics. These resources made a significant difference in my study routine and overall performance. I went into the exam feeling confident and well-prepared.
The PR000041 materials for the Informatica certification exam were invaluable. They provided detailed, concise explanations for each topic, helping me grasp the entire syllabus. After studying with these resources, I was able to tackle the final test questions confidently and successfully.
Thanks to the comprehensive study guides and video courses, I aced the PR000041 exam. The exam dumps were spot on and helped me understand the types of questions to expect. The certification exam was much less intimidating thanks to their excellent prep materials. So, I highly recommend their services for anyone preparing for this certification exam.
Achieving my Informatica certification was a seamless experience. The detailed study guide and practice questions ensured I was fully prepared for PR000041. The customer support was responsive and helpful throughout my journey. Highly recommend their services for anyone preparing for their certification test.
I couldn't be happier with my certification results! The study materials were comprehensive and easy to understand, making my preparation for the PR000041 stress-free. Using these resources, I was able to pass my exam on the first attempt. They are a must-have for anyone serious about advancing their career.
The practice exams were incredibly helpful in familiarizing me with the actual test format. I felt confident and well-prepared going into my PR000041 certification exam. The support and guidance provided were top-notch. I couldn't have obtained my Informatica certification without these amazing tools!
The materials provided for the PR000041 were comprehensive and very well-structured. The practice tests were particularly useful in building my confidence and understanding the exam format. After using these materials, I felt well-prepared and was able to solve all the questions on the final test with ease. Passing the certification exam was a huge relief! I feel much more competent in my role. Thank you!
The certification prep was excellent. The content was up-to-date and aligned perfectly with the exam requirements. I appreciated the clear explanations and real-world examples that made complex topics easier to grasp. I passed PR000041 successfully. It was a game-changer for my career in IT!


