
- Home
- Cloudera Certifications
- CCA-500 Cloudera Certified Administrator for Apache Hadoop (CCAH) Dumps
Pass Cloudera CCA-500 Exam in First Attempt Guaranteed!
Get 100% Latest Exam Questions, Accurate & Verified Answers to Pass the Actual Exam!
30 Days Free Updates, Instant Download!


CCA-500 Premium File
- Premium File 60 Questions & Answers. Last Update: Oct 30, 2026
Whats Included:
- Latest Questions
- 100% Accurate Answers
- Fast Exam Updates
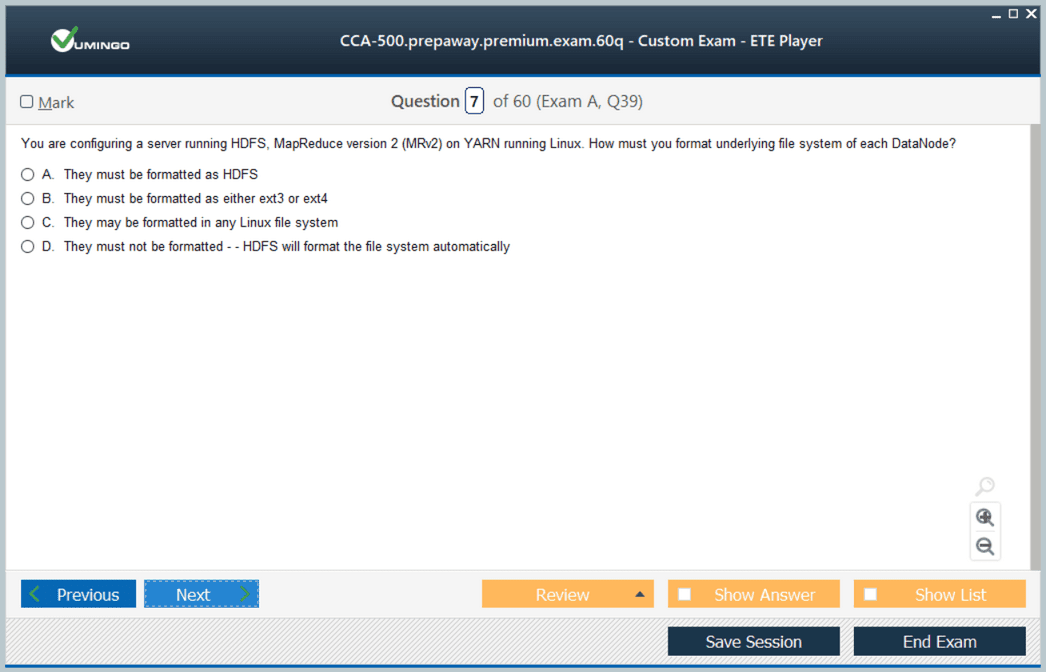
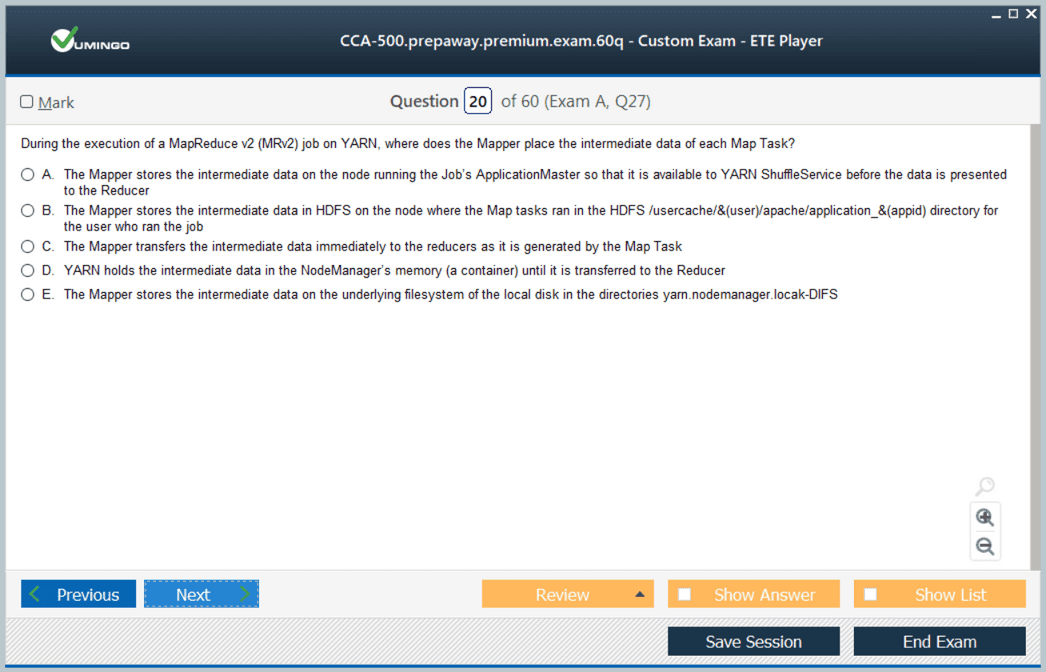
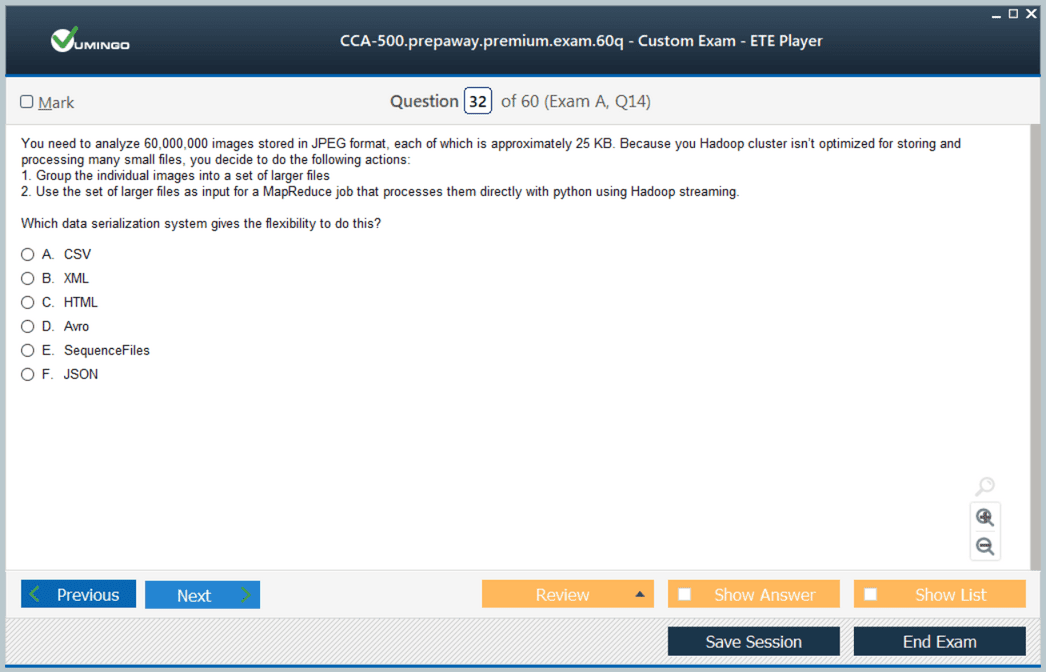
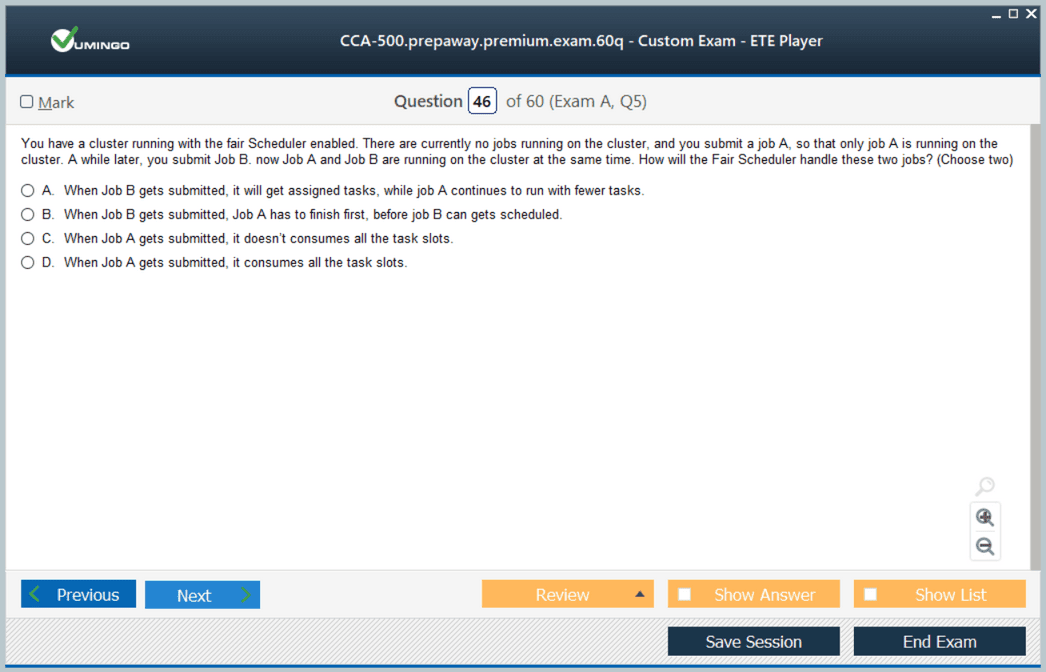
Last Week Results!
 83% students found the test questions almost same
CCA-500: Legacy Cloudera Administrator for Apache Hadoop
CCA-500 was the Cloudera Certified Administrator for Apache Hadoop exam used for the older CCAH certification. Cloudera’s archived certification material states that it was replaced by CCA131, stopped being available for purchase after April 30, 2017, and had its final exam session on May 31, 2017. CCA-500 is therefore a historical administration exam, not a current Cloudera scheduling target.
The exam represented a period when Hadoop administrators were expected to understand HDFS, MapReduce-era cluster behavior, operating-system prerequisites, installation, configuration, security, resource management, monitoring, troubleshooting, and routine operations. Those topics still teach distributed-systems discipline, but the surrounding Cloudera platform has changed substantially. Anyone using old CCA-500 notes should separate durable Hadoop concepts from product versions, commands, and operational practices tied to that generation.
The broader Cloudera certification family provides current vendor context. The historical CCD-410 Cloudera Certified Developer for Apache Hadoop is also useful for understanding the developer side of the same ecosystem: administrators protected cluster reliability while developers designed jobs that consumed its storage and compute resources.
HDFS administration begins with understanding how data is distributed
HDFS is built around the idea that large files can be divided into blocks and stored across multiple machines with replication for fault tolerance. An administrator needs to understand the roles of metadata services and data-storage processes, how block placement affects resilience, and what happens when a node disappears. Capacity is not only a raw-disk question; replication, reserved space, temporary data, and uneven utilization all change how much usable room the cluster really has.
Operational reasoning should follow the path of a read or write. Ask where metadata is consulted, which nodes participate, what acknowledgements are required, and how failures are handled. That mental model explains why a full disk, unavailable node, metadata problem, or network partition produces different symptoms. Memorizing daemon names is less useful than being able to trace which component should own a given failure.
High availability changes the failure model because metadata services can have active and standby roles rather than one irreplaceable process. Even in a historical study context, candidates should understand the operational objective: remove obvious single points of failure, keep metadata state synchronized, and test failover paths. A design is not highly available merely because two servers exist; the transition mechanism and client behavior have to work when the active service disappears.
Cluster installation and configuration require dependency awareness
Hadoop clusters sit on top of operating systems, networks, storage devices, Java runtimes, name resolution, time synchronization, and service accounts. A configuration can look correct in one file while the underlying host prevents it from working. Historical CCA-500 preparation therefore emphasized system prerequisites, directories, permissions, configuration files, and the relationship between cluster-wide settings and node-specific values.
Good administration changes one variable at a time and records the result. Before rolling a configuration change across many machines, test it on a representative node or controlled environment, understand whether a restart is required, and know how to roll back. That habit remains relevant in modern platforms even when automation replaces hand-edited configuration files.
Node lifecycle procedures are another important administrative skill. Adding capacity requires consistent software, configuration, network access, and storage permissions. Removing a node should be deliberate so blocks and workloads can move safely before hardware is taken away. Decommissioning is different from abruptly shutting a server down, and a good administrator knows how to confirm that the cluster has returned to the intended replication and health state afterward.
Resource management connects workload demand with finite cluster capacity
Distributed processing competes for CPU, memory, network bandwidth, and disk throughput. Resource management attempts to allocate those resources fairly and predictably while keeping the cluster productive. Administrators need to distinguish a cluster that lacks capacity from one that uses capacity poorly. A single oversized job, an unbalanced queue, or data skew can create symptoms that resemble a hardware shortage.
Historical Hadoop environments often forced administrators to reason about job slots, schedulers, queue policies, and resource limits. Modern tooling changes the control surfaces, but the underlying question remains: which workload is consuming which constrained resource, and is that behavior expected? Capacity planning becomes more accurate when it is based on observed workload profiles rather than headline node counts.
Workload isolation also protects predictable service. Batch analytics, interactive queries, and maintenance jobs can have very different latency and throughput expectations. Queue policies, priorities, and capacity controls should reflect those expectations instead of treating every submitted job as equally urgent. Administrators need enough application context to know whether a busy cluster is productively saturated or whether one workload is harming higher-value work.
Operational change should be observable. When an administrator modifies a queue, replication policy, memory setting, or service configuration, record the previous value and define the metric that should improve. If the expected behavior does not change, revert or investigate rather than stacking additional changes. This controlled approach reduces configuration drift and makes post-incident analysis possible.
Security is a layered operational system, not a single setting
Cluster security depends on identity, authentication, authorization, transport protection, host hardening, service accounts, file permissions, and auditability. Turning on one security mechanism does not secure every data path. Administrators must know which service is authenticating a user, which policy authorizes access, and where credentials or tickets are stored. Misconfiguration can either expose data or lock legitimate workloads out of resources.
The safest study method is to draw trust boundaries. Mark clients, edge nodes, management services, worker nodes, storage, and external systems, then identify how identities cross those boundaries. This exposes gaps that a checklist can hide. It also helps when comparing older Kerberos-centered Hadoop material with newer identity and governance services in current data platforms.
Monitoring needs baselines before alerts become meaningful
An alert is useful only when it reflects a meaningful deviation or risk. Administrators should establish normal ranges for storage utilization, failed tasks, service availability, JVM health, queue behavior, network throughput, and node responsiveness. Without a baseline, teams either ignore noisy alerts or miss slow degradation. Monitoring should answer whether the cluster is healthy, whether performance is changing, and which component deserves investigation first.
Logs, counters, service metrics, and operating-system telemetry provide different layers of evidence. The most efficient troubleshooters correlate them rather than reading one log file in isolation. If jobs slow down, for example, compare application behavior with disk, network, memory, queue, and node-health signals before deciding that the application itself is at fault.
Small-file growth deserves monitoring because it can create a metadata problem even when total data volume looks reasonable. Millions of tiny objects increase namespace overhead and often produce inefficient processing patterns. Administrators should distinguish storage capacity from metadata scalability and work with data producers to consolidate or redesign pipelines when file counts grow faster than the system was intended to handle.
Backup and recovery planning must distinguish data from metadata
Distributed replication is not the same as backup. Replication protects against certain node failures, but it does not automatically protect against deletion, corruption, administrative mistakes, or a failure that affects the entire cluster. Administrators need recovery plans for critical metadata, configuration, security material, and important datasets. The recovery procedure should be tested, not merely documented.
Historical Hadoop environments made metadata protection especially important because the namespace and block mapping were central to cluster operation. A useful exercise is to list every component whose loss would prevent service restoration and identify where its backup is stored, how often it is captured, and how the team verifies that it can be restored.
Performance troubleshooting starts with the bottleneck, not the tuning knob
When a cluster is slow, the correct response is not to change random memory or replication settings. First define the symptom: slow reads, long job startup, reducer stragglers, network saturation, disk wait, or a failing service. Then collect evidence and isolate the constrained resource. Tuning without measurement can move a bottleneck or create a new failure.
Data layout and workload design also matter. A cluster with many tiny files can stress metadata services; poorly partitioned data can create hotspots; large shuffle volumes can saturate networks. The discussion of Hadoop and MongoDB for big-data workloads is useful here because it reinforces a larger point: technology fit depends on access patterns, consistency needs, latency expectations, and operational cost, not only data size.
CCA-500 remains useful as a historical operations syllabus
CCA-500 is most valuable today when used to understand the operational mechanics of a classic Hadoop cluster. Build a small lab, observe HDFS behavior, inspect service logs, simulate a failed worker, watch replication recover, and trace a distributed job from submission to completion. Hands-on experiments make the historical objectives concrete and reveal which concepts survive platform changes.
For current credential planning, use Cloudera’s live training and certification information rather than an old CCA-500 exam plan. The code itself is retired, and the certification program has changed more than once since 2017. The durable lesson is operational discipline: understand service dependencies, measure before tuning, protect metadata and data, document change, and design recovery before a failure forces the issue.
A useful operations drill is to write a short runbook for common events: a failed data node, a full filesystem, a service that will not start, a queue consuming excessive resources, or a planned node replacement. For each event, list the evidence to collect before change, the safest corrective action, and the checks that prove recovery. Runbooks make the historical objectives practical and reinforce the change-control discipline expected in modern data platforms.
That discipline remains valuable even when the modern platform automates many of the manual steps the original administrator had to perform.
Why customers love us?
What do our customers say?
The resources provided for the Cloudera certification exam were exceptional. The exam dumps and video courses offered clear and concise explanations of each topic. I felt thoroughly prepared for the CCA-500 test and passed with ease.
Studying for the Cloudera certification exam was a breeze with the comprehensive materials from this site. The detailed study guides and accurate exam dumps helped me understand every concept. I aced the CCA-500 exam on my first try!
I was impressed with the quality of the CCA-500 preparation materials for the Cloudera certification exam. The video courses were engaging, and the study guides covered all the essential topics. These resources made a significant difference in my study routine and overall performance. I went into the exam feeling confident and well-prepared.
The CCA-500 materials for the Cloudera certification exam were invaluable. They provided detailed, concise explanations for each topic, helping me grasp the entire syllabus. After studying with these resources, I was able to tackle the final test questions confidently and successfully.
Thanks to the comprehensive study guides and video courses, I aced the CCA-500 exam. The exam dumps were spot on and helped me understand the types of questions to expect. The certification exam was much less intimidating thanks to their excellent prep materials. So, I highly recommend their services for anyone preparing for this certification exam.
Achieving my Cloudera certification was a seamless experience. The detailed study guide and practice questions ensured I was fully prepared for CCA-500. The customer support was responsive and helpful throughout my journey. Highly recommend their services for anyone preparing for their certification test.
I couldn't be happier with my certification results! The study materials were comprehensive and easy to understand, making my preparation for the CCA-500 stress-free. Using these resources, I was able to pass my exam on the first attempt. They are a must-have for anyone serious about advancing their career.
The practice exams were incredibly helpful in familiarizing me with the actual test format. I felt confident and well-prepared going into my CCA-500 certification exam. The support and guidance provided were top-notch. I couldn't have obtained my Cloudera certification without these amazing tools!
The materials provided for the CCA-500 were comprehensive and very well-structured. The practice tests were particularly useful in building my confidence and understanding the exam format. After using these materials, I felt well-prepared and was able to solve all the questions on the final test with ease. Passing the certification exam was a huge relief! I feel much more competent in my role. Thank you!
The certification prep was excellent. The content was up-to-date and aligned perfectly with the exam requirements. I appreciated the clear explanations and real-world examples that made complex topics easier to grasp. I passed CCA-500 successfully. It was a game-changer for my career in IT!


