
- Home
- IBM Certifications
- C2090-930 IBM SPSS Modeler Professional v3 Dumps
Pass IBM C2090-930 Exam in First Attempt Guaranteed!
Get 100% Latest Exam Questions, Accurate & Verified Answers to Pass the Actual Exam!
30 Days Free Updates, Instant Download!


C2090-930 Premium File
- Premium File 60 Questions & Answers. Last Update: Nov 13, 2026
Whats Included:
- Latest Questions
- 100% Accurate Answers
- Fast Exam Updates
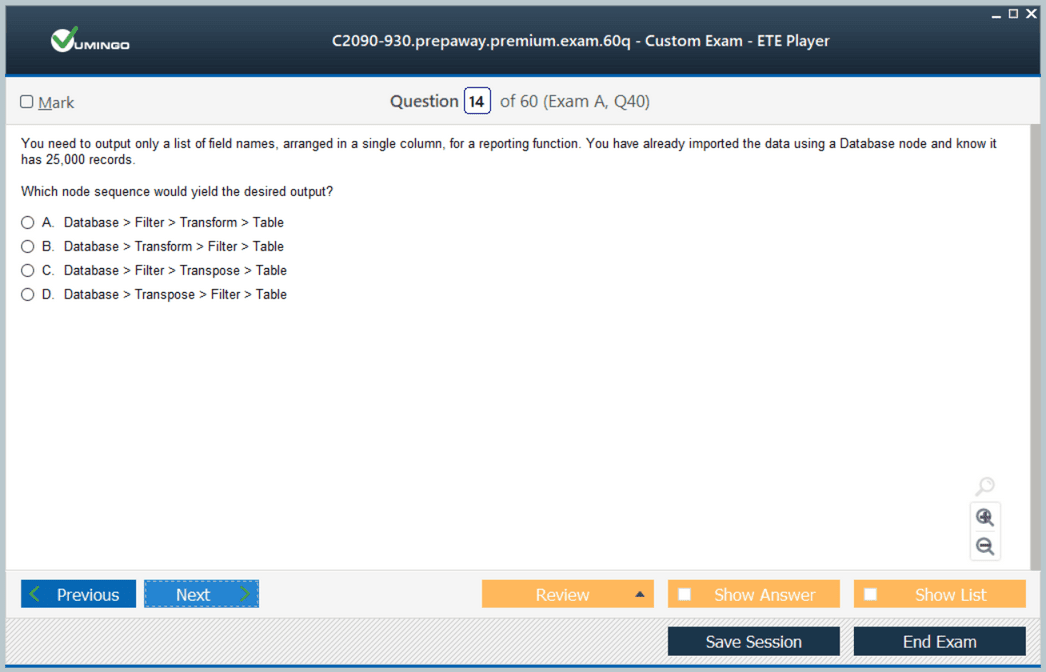
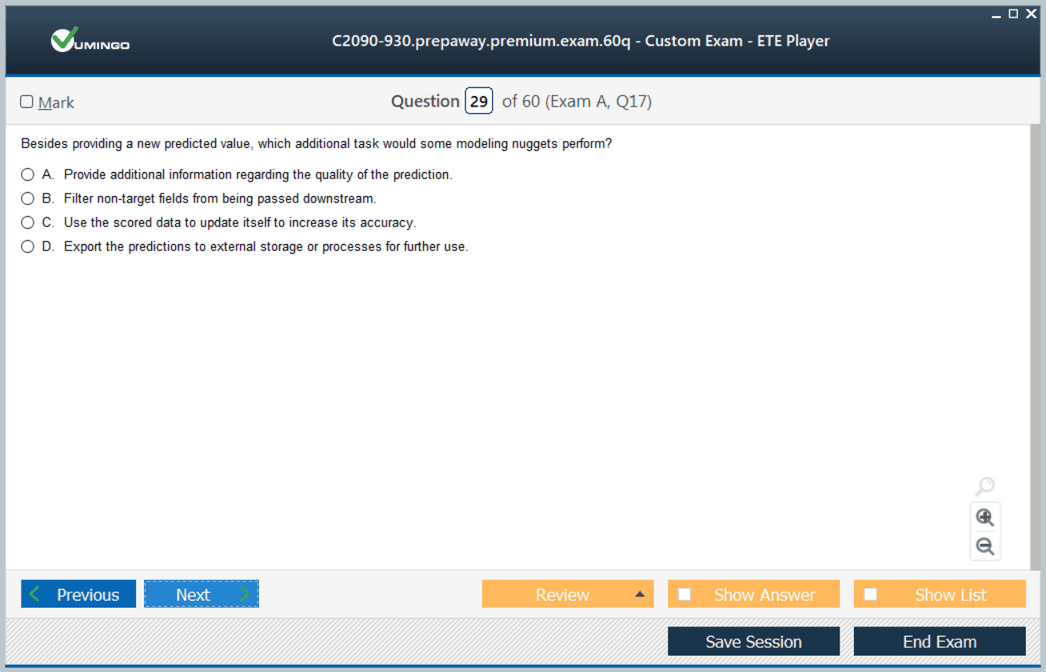
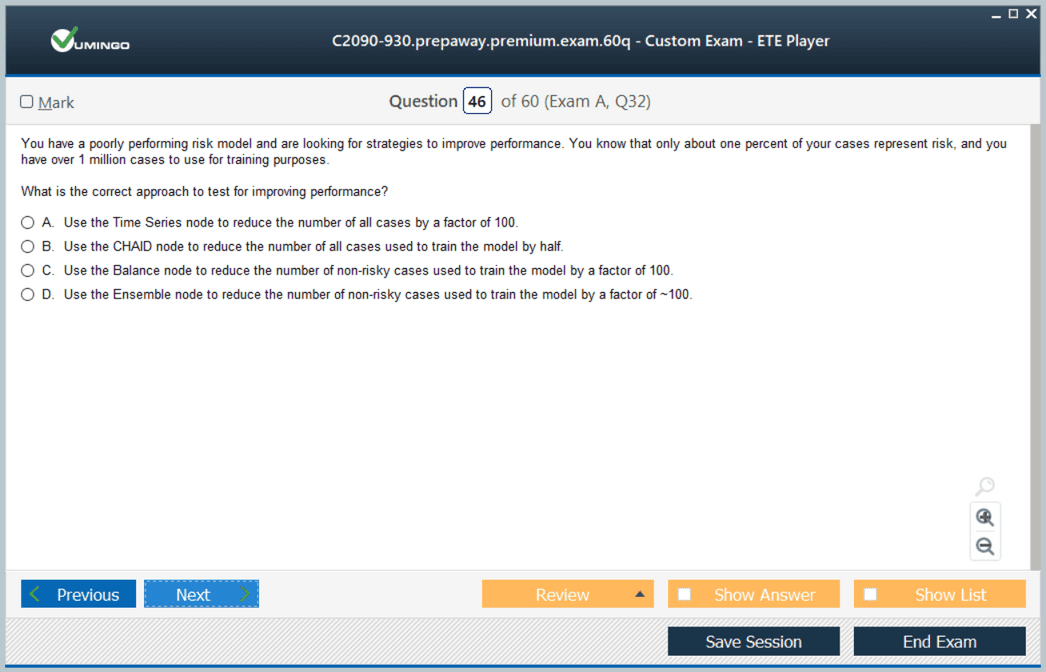
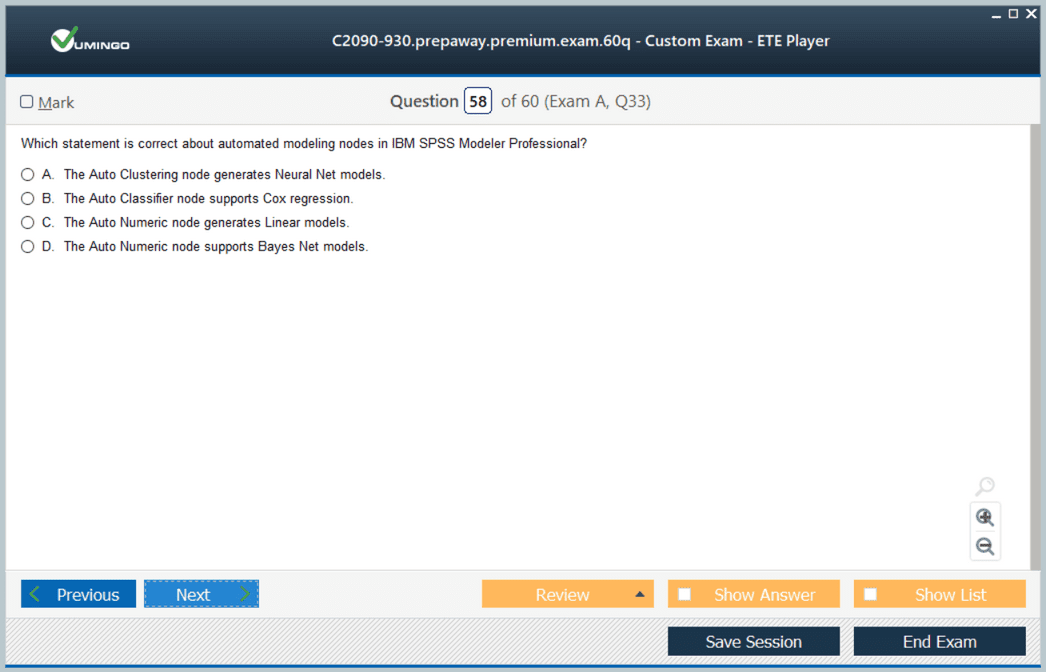
Last Week Results!
 83% students found the test questions almost same
IBM C2090-930: SPSS Modeler Professional v3
C2090-930 is a withdrawn IBM exam for the IBM Certified Specialist - SPSS Modeler Professional v3 credential. IBM’s certification record explicitly marks the certification withdrawn on June 30, 2023 and the exam status as withdrawn. That makes the page a legacy certification reference rather than a current exam-preparation destination.
The exam’s technical scope remains valuable because it is organized around a complete analytical workflow: business understanding, data preparation, data understanding, modeling, evaluation, and deployment. IBM’s published objectives also reference CRISP-DM and SPSS Modeler nodes used for transformations, sampling, visualization, and predictive modeling. Those ideas continue to matter even as product versions and credential programs change.
C2090-930 belongs to the historical IBM certifications portfolio. Learners can use the old blueprint to understand structured data-mining practice, but anyone seeking a credential now should consult IBM’s current analytics and AI certification catalog.
CRISP-DM connects business questions to technical modeling work
Predictive modeling is useful only when it addresses a defined business objective. CRISP-DM starts by understanding that objective, translating it into a data-mining goal, and deciding how success will be evaluated. This prevents teams from optimizing a statistical metric that has little operational value.
The broader field of data mining includes classification, prediction, segmentation, association, and other ways of finding useful structure in data. SPSS Modeler provides a visual workflow for applying many of those techniques, but the business question should determine which technique is appropriate.
Projects are iterative. Findings during preparation may show that the original objective is unrealistic, and model evaluation may expose missing variables or biased data. CRISP-DM is better understood as a cycle than as a rigid one-way checklist.
Data understanding should happen before aggressive transformation
Analysts need to examine distributions, missing values, outliers, category frequencies, target balance, and relationships before building a model. Visualizations and summary statistics can reveal data-quality issues and can also show that a proposed predictor has little variation or leaks information from the future.
Exploratory data analysis provides the reasoning framework for this stage. The goal is not to produce attractive charts but to learn how the dataset was generated, where it may be unreliable, and what patterns deserve further investigation.
Sampling needs caution. A convenient sample can distort rare events, seasonal patterns, or important customer segments. The analysis should preserve the population characteristics necessary for the intended decision.
Data preparation determines what the model is allowed to learn
IBM’s C2090-930 objectives include transformations, integration, sampling, partitioning, balancing, selection, filtering, and aggregation. These are not housekeeping tasks; each one changes the information presented to the model and can therefore change the resulting predictions.
Missing values need a defined treatment based on why they are missing. Replacing every blank with a single default can create an artificial signal. Categorical encoding, normalization, derivation, and outlier handling should likewise be justified by the algorithm and business context.
Preparation must avoid leakage. If a field contains information that would only be known after the prediction time, a model can appear extremely accurate during testing and fail in real use. Partitioning and feature selection should preserve the boundary between what was knowable then and what is known now.
Descriptive statistics and inferential reasoning support model interpretation
SPSS Modeler users benefit from understanding measures such as mean, median, variance, distributions, correlations, and sampling behavior. The distinction between descriptive and inferential statistics is important because summarizing the observed dataset is different from making claims about a wider population.
Statistical relationships also do not automatically establish causation. A predictive variable can be useful without being causal, but stakeholders need that distinction when they interpret the model or use it to change policy.
Uncertainty should be communicated. A model output is not an oracle; thresholds, confidence, class imbalance, and the cost of false positives or false negatives all influence how predictions should be used.
Algorithm choice should match the target, data, and decision
Different models make different assumptions and produce different forms of output. Classification predicts categories, regression predicts numeric values, clustering groups similar cases, and association methods discover relationships among items or events. Some algorithms emphasize interpretability while others can model more complex patterns.
The overview of machine-learning algorithms and use cases helps explain why there is no universally best model. The right choice depends on data size, feature types, nonlinearity, operational constraints, and how much explanation the decision requires.
Model comparison should use a metric aligned with the business problem. Accuracy can be misleading when one class dominates. Precision, recall, lift, error cost, or other measures may better reflect the consequences of correct and incorrect decisions.
Training and testing must remain separated
A model should be evaluated on data that did not influence its fitting decisions. Partitioning data into training and testing sets provides a basic check against overfitting, while validation or cross-validation can support model and parameter selection.
Repeatedly examining the test set and changing the model to improve that result effectively turns the test data into part of training. Teams should preserve an independent final evaluation or use disciplined resampling so performance estimates remain meaningful.
Temporal data needs special handling. Randomly mixing future records into a training sample for a model that will make chronological predictions can create leakage and unrealistic performance.
Evaluation should include business cost and operational behavior
A statistically strong model may still be unusable if it requires unavailable inputs, scores too slowly, produces unstable segments, or cannot meet governance requirements. Evaluation should therefore include deployment constraints and the cost of different error types.
Confusion matrices, gains, lift, ROC-style analysis, residuals, and other diagnostics help analysts understand model behavior from different angles. No single metric describes every consequence. Segment-level evaluation can reveal that a model performs well overall but poorly for an important subgroup.
Stakeholders should know what action follows a prediction. A churn score that is never connected to a retention process creates analytical output without business impact.
Deployment turns a model stream into a maintained business process
SPSS Modeler streams can combine source, preparation, modeling, evaluation, and scoring nodes. Moving from an analyst’s workstation to repeatable operational scoring requires controlled data connections, versioning, scheduling or integration, output handling, and monitoring.
Models also decay. Customer behavior, products, fraud patterns, economic conditions, and data collection can change after deployment. Teams should monitor input drift, output distributions, and performance where outcomes become available, then retrain or retire models when evidence supports it.
Governance should preserve which data, transformations, algorithm version, and parameters produced a deployed model. That lineage is necessary for audit, troubleshooting, and reproducibility.
Feature engineering deserves special attention because derived variables often determine whether a model captures useful signal. Ratios, time intervals, aggregated history, and categorical groupings can make a relationship easier for an algorithm to learn, but they should be created from information that would exist at scoring time and should remain understandable to reviewers.
Class imbalance is another common problem. When the event of interest is rare, a model can achieve high overall accuracy by predicting the majority class almost every time. Sampling, balancing, weighting, threshold selection, and suitable evaluation metrics should be considered together rather than applying one technique automatically.
Reproducibility matters even in a visual modeling environment. Source versions, random seeds where applicable, node settings, partition logic, and transformations should be preserved so another analyst can recreate the result. Screenshots of a final chart are not enough to reconstruct the analytical process.
Model governance becomes more important when predictions affect people, money, or regulated decisions. Teams should document intended use, excluded use, data limitations, validation results, ownership, and retirement criteria. A technically accurate model can still create risk when it is applied to a population or decision it was never tested for.
C2090-930 is a retired credential, but its workflow remains instructive
The boundaries between data science, machine learning, and data analytics can be blurry in job titles, yet C2090-930’s workflow is useful across all three: define the problem, understand the data, prepare it carefully, choose and evaluate methods, then operationalize results responsibly.
IBM’s official record removes ambiguity about the certification status: the exam is withdrawn. Candidates should not build a new exam plan around C2090-930 or assume third-party practice material indicates current availability.
Responsible analytical practice also checks whether the training data represents the population on which the model will be used. Missing regions, customer types, time periods, or rare outcomes can create performance gaps that an aggregate metric hides. Evaluation should inspect meaningful segments when the business decision can affect them differently.
Deployment monitoring should include the data pipeline as well as the model. A change in upstream coding, a new category value, or a broken join can alter inputs even when the scoring service remains healthy. Data-quality alarms can therefore be an early warning of model failure.
Interpretability should match the decision context. A complex model can be appropriate when predictive performance is the priority and the result is reviewed by specialists, while a regulated or high-impact process may require explanations that are understandable to nontechnical reviewers. Model selection should include that operational requirement.
Analytical documentation should state what the target means and when it is observed. Ambiguous labels are a common source of leakage and evaluation errors: if “churn” is defined differently in training data and production reporting, the same model score can be interpreted in incompatible ways.
The legacy blueprint is still valuable for professionals learning SPSS Modeler or structured predictive-modeling practice. Use it as a historical skills map, pair it with the documentation for the SPSS Modeler version actually in use, and rely on IBM’s current credential catalog for present-day certification decisions.
Why customers love us?
What do our customers say?
The resources provided for the IBM certification exam were exceptional. The exam dumps and video courses offered clear and concise explanations of each topic. I felt thoroughly prepared for the C2090-930 test and passed with ease.
Studying for the IBM certification exam was a breeze with the comprehensive materials from this site. The detailed study guides and accurate exam dumps helped me understand every concept. I aced the C2090-930 exam on my first try!
I was impressed with the quality of the C2090-930 preparation materials for the IBM certification exam. The video courses were engaging, and the study guides covered all the essential topics. These resources made a significant difference in my study routine and overall performance. I went into the exam feeling confident and well-prepared.
The C2090-930 materials for the IBM certification exam were invaluable. They provided detailed, concise explanations for each topic, helping me grasp the entire syllabus. After studying with these resources, I was able to tackle the final test questions confidently and successfully.
Thanks to the comprehensive study guides and video courses, I aced the C2090-930 exam. The exam dumps were spot on and helped me understand the types of questions to expect. The certification exam was much less intimidating thanks to their excellent prep materials. So, I highly recommend their services for anyone preparing for this certification exam.
Achieving my IBM certification was a seamless experience. The detailed study guide and practice questions ensured I was fully prepared for C2090-930. The customer support was responsive and helpful throughout my journey. Highly recommend their services for anyone preparing for their certification test.
I couldn't be happier with my certification results! The study materials were comprehensive and easy to understand, making my preparation for the C2090-930 stress-free. Using these resources, I was able to pass my exam on the first attempt. They are a must-have for anyone serious about advancing their career.
The practice exams were incredibly helpful in familiarizing me with the actual test format. I felt confident and well-prepared going into my C2090-930 certification exam. The support and guidance provided were top-notch. I couldn't have obtained my IBM certification without these amazing tools!
The materials provided for the C2090-930 were comprehensive and very well-structured. The practice tests were particularly useful in building my confidence and understanding the exam format. After using these materials, I felt well-prepared and was able to solve all the questions on the final test with ease. Passing the certification exam was a huge relief! I feel much more competent in my role. Thank you!
The certification prep was excellent. The content was up-to-date and aligned perfectly with the exam requirements. I appreciated the clear explanations and real-world examples that made complex topics easier to grasp. I passed C2090-930 successfully. It was a game-changer for my career in IT!


