
- Home
- VMware Certifications
- 5V0-34.19 VMware vRealize Operations 7.5 Dumps
Pass VMware 5V0-34.19 Exam in First Attempt Guaranteed!
Get 100% Latest Exam Questions, Accurate & Verified Answers to Pass the Actual Exam!
30 Days Free Updates, Instant Download!


5V0-34.19 Premium File
- Premium File 50 Questions & Answers. Last Update: Oct 01, 2026
Whats Included:
- Latest Questions
- 100% Accurate Answers
- Fast Exam Updates
Last Week Results!
 83% students found the test questions almost same
All VMware 5V0-34.19 certification exam dumps, study guide, training courses are Prepared by industry experts. PrepAway's ETE files povide the 5V0-34.19 VMware vRealize Operations 7.5 practice test questions and answers & exam dumps, study guide and training courses help you study and pass hassle-free!
5V0-34.19 VMware vRealize Operations 7.5: Learning Performance and Capacity from a Retired Blueprint
5V0-34.19 was the VMware vRealize Operations 7.5 exam. Broadcom lists it as retired on February 28, 2022, so it is not a current certification target. Its value now is historical and technical: the blueprint captures monitoring, capacity, policy, cluster architecture, dashboards, and troubleshooting concepts that continue to matter in modern infrastructure operations.
vRealize Operations was built to answer a deceptively difficult question: what does healthy infrastructure look like over time? CPU, memory, storage, network, configuration, alerts, and application behavior create more signals than a human can evaluate manually. The platform organizes those signals into objects, relationships, policies, symptoms, and forecasts so operators can distinguish a real risk from ordinary variation.
Candidates seeking newer material should compare this retired code with the later 5V0-35.21 VMware vRealize Operations Specialist. The product family later adopted Aria branding, but the enduring preparation goal is the same: understand how monitoring data becomes operational decisions rather than memorizing dashboard locations.
Objects and adapters define what the monitoring system can actually know
Every metric belongs to an object, and every object enters the platform through an adapter, integration, or discovery process. Before reading an alert, understand what object is being monitored, which relationship connects it to the rest of the environment, and how fresh the data is. Missing or stale collection can create a false sense of health.
Relationships are as important as individual metrics. A virtual machine depends on compute, datastore, network, and management layers, so an application symptom may be caused by an object several hops away. Practice navigating from symptom to dependency instead of looking only at the first red icon.
Collection design should also account for scale. Remote collectors, adapter instances, and cluster sizing affect how reliably data arrives. Monitoring architecture needs the same capacity and failure planning as the infrastructure it observes.
Adapter health should be monitored as data quality, not only as connectivity. Delayed collection, missing object relationships, renamed resources, or stale credentials can make an apparently healthy analytics platform reason from incomplete evidence. Operators should know the expected collection interval and object count for critical sources so they can recognize when dashboards are becoming less trustworthy before alerts and capacity forecasts drift away from reality.
Policies turn raw telemetry into environment-specific expectations
A threshold that is useful for one cluster may be meaningless for another. Policies let administrators tune capacity models, alert behavior, workload assumptions, and object treatment so that the system reflects service intent. The important skill is knowing why a policy differs, not merely where the setting is stored.
Build policy hierarchies carefully. A broad base policy can establish organization-wide behavior, while more specific policies adapt to production, development, edge, or high-performance workloads. Too many exceptions make the model impossible to reason about; too few make alerts noisy or misleading.
Always test policy changes against representative objects. A new threshold can suppress legitimate warnings just as easily as it can reduce noise. Monitoring configuration should be changed with the same discipline as production infrastructure.
Policy inheritance should be tested whenever new groups or business tiers are introduced. A virtual machine can inherit thresholds from several organizational concepts even though operators expect one policy to dominate. Use a small set of test objects to prove effective policy before changing thousands of resources. The same discipline helps prevent alert storms after acquisitions, new clusters, or service-tier changes because the monitoring system's interpretation of “normal” remains deliberate.
Symptoms and alerts should describe a condition that has an owner
A symptom is evidence; an alert combines evidence into an actionable interpretation. Good alert design identifies the object, the condition, probable cause, impact, and useful next action. If an alert cannot tell an operator what to investigate, it becomes background noise no matter how technically accurate it is.
Avoid evaluating one metric in isolation. CPU contention, storage latency, memory pressure, and network loss can produce similar application complaints. Correlate timing and dependency relationships before deciding which metric is causal. The broader approach in observability by design reinforces the idea that useful signals exist to support decisions.
Alert volume should be measured. Track repeated alerts, unowned conditions, acknowledgements without remediation, and notifications that never change behavior. Those are signs that the monitoring design needs refinement rather than more dashboards.
Capacity models require understanding both demand and policy assumptions
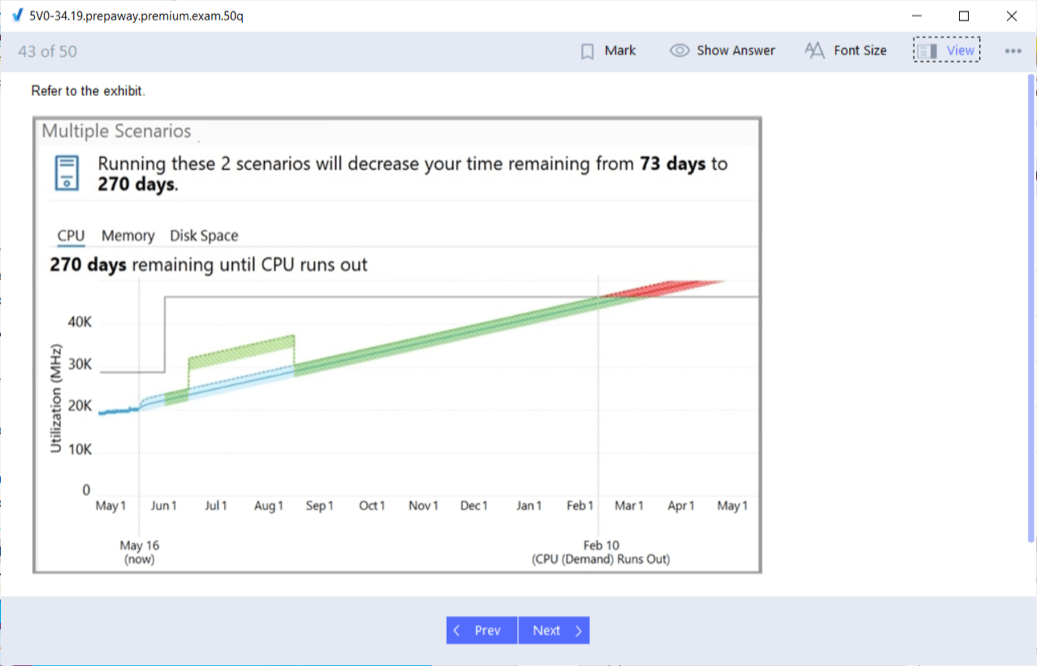
vRealize Operations can estimate remaining capacity and time based on historical behavior, configured allocation, growth patterns, and policy. Forecasts are useful only when their assumptions match how the environment is actually operated. A cluster with aggressive overcommit or seasonal demand can mislead a model that assumes stable usage.
Separate physical headroom from business headroom. An infrastructure team may technically be able to place more workloads while still violating a maintenance, resilience, or performance target. Capacity planning should include host loss, storage recovery, and maintenance windows rather than reporting only steady-state utilization.
When a forecast changes sharply, investigate the data behind it. A new workload, collection gap, one-time batch process, or policy change can alter the projection. Capacity analytics are strongest when operators can explain the model rather than treating the number as an oracle.
Reclamation recommendations also need operational judgment. Powered-off virtual machines, snapshots, oversized memory reservations, and idle capacity may look wasteful, but some represent recovery, maintenance, licensing, or burst requirements. Before accepting a recommendation, identify the business owner and the assumption that made the resource appear reclaimable. Good capacity management converts analytics into a decision with accountable risk rather than treating every efficiency suggestion as an automatic action.
Dashboards, views, and reports should answer different operational questions
Dashboards are useful for real-time situational awareness, views help present object data in reusable forms, and reports package selected information for scheduled or offline consumption. Do not build all three from the same metric list. Start with the question each audience needs answered.
An operations dashboard may emphasize active risk, dependency, and change timing. A capacity review may show growth and remaining headroom. An executive report may focus on service health, trend, and unresolved exposure. The platform becomes more valuable when each presentation layer is intentionally scoped.
Measure whether dashboards lead to action. If operators ignore a widget or always open another tool before trusting it, the view may lack context. Replace decorative metrics with evidence tied to decisions and ownership.
Groups and super metrics let administrators express environment-specific logic
Dynamic groups can collect objects by properties, relationships, or business purpose, allowing policies and dashboards to follow the way the organization actually operates. A good group is stable enough to be trustworthy and flexible enough to update when inventory changes.
Super metrics combine raw measurements into derived indicators. They are useful when a business or operational question cannot be answered by one native counter. Document the formula, units, expected range, and failure interpretation so that future administrators can understand what the metric is claiming.
Custom logic should be governed like code. Test it on known cases, version significant changes, and remove metrics or groups that no longer serve a decision. Monitoring debt accumulates when old customizations remain long after the service they represented has changed.
Cluster architecture and high availability protect the monitoring function itself
A monitoring platform that disappears during an infrastructure incident is least useful when it is needed most. Understand node roles, data distribution, collection dependencies, and how failure changes cluster behavior. Plan capacity so that surviving nodes can continue operating after a fault.
High availability is a system property, and that principle applies here too. A redundant analytics cluster still depends on DNS, time, storage, credentials, connectivity, and the monitored endpoints. Test those dependencies instead of assuming node redundancy solves every failure.
Recovery planning should include configuration, historical data, integrations, and credentials. Decide what must be restored first to regain useful visibility and what can be reconstructed later.
Troubleshooting performance starts by separating symptom, bottleneck, and cause
A high counter is not automatically a problem. CPU utilization may be high because the workload is productive; low utilization may coexist with CPU ready or storage latency. Build hypotheses from the user-visible symptom, then use metrics to test whether compute, memory, storage, network, or configuration can explain it.
Compare affected and healthy objects. Baselines often reveal more than static thresholds because they show what changed. Monitoring baselines reinforce the same discipline: deviation has meaning only when normal behavior is known.
Make one change at a time when tuning. Resizing CPU, changing reservations, migrating a VM, or moving storage can alter several metrics. Controlled changes preserve evidence and prevent an improvement from being attributed to the wrong action.
Time correlation is particularly valuable in virtual infrastructure because a single host event can affect many workloads at once. Compare guest symptoms with host CPU scheduling, datastore latency, network errors, migration activity, backup windows, and recent configuration changes. A spike that begins at exactly the same time across several unrelated virtual machines usually points to a shared dependency, while one isolated guest suggests a narrower workload or operating-system cause.
Retired vRealize Operations material is most useful when translated into current operations practice
Because 5V0-34.19 is retired, do not reproduce every 7.5 interface detail. Preserve the analytical method: collect trustworthy data, model relationships, tune policies, build actionable alerts, forecast capacity, and validate changes. Those skills remain relevant across newer VMware and VCF operations tooling.
Candidates moving into broader cloud operations can connect these ideas with VMware Cloud Foundation administration and advanced cloud-management work such as 3V0-32.23. The value is not the old badge; it is the ability to explain why infrastructure is unhealthy and what action should follow.
A useful final lab is to create a monitoring design from scratch for a small virtual environment. Define object inventory, relationships, collection frequency, policies, capacity assumptions, alerts, dashboards, and incident evidence. If each element supports a specific operational decision, the retired blueprint has been converted into durable observability skill.
VMware 5V0-34.19 practice test questions and answers, training course, study guide are uploaded in ETE Files format by real users. Study and Pass 5V0-34.19 VMware vRealize Operations 7.5 certification exam dumps & practice test questions and answers are to help students.
- 2V0-17.25 - VMware Cloud Foundation 9.0 Administrator
- 2V0-13.25 - VMware Cloud Foundation 9.0 Architect
- 3V0-25.25 - Advanced VMware Cloud Foundation 9.0 Networking
- 2V0-16.25 - VMware vSphere Foundation 9.0 Administrator
- 3V0-21.25 - Advanced VMware Cloud Foundation 9.0 Automation
- 2V0-21.23 - VMware vSphere 8.x Professional
- 3V0-24.25 - VMware Certified Advanced Professional - VMware Cloud Foundation VKS
- 2V0-15.25 - VMware Cloud Foundation 9.0 Support
- 2V0-41.24 - VMware NSX 4.X Professional V2
- 2V0-72.22 - Professional Develop VMware Spring
- 2V0-51.23 - VMware Horizon 8.x Professional
- 2V0-11.25 - VMware Cloud Foundation 5.2 Administrator
- 3V0-32.23 - Cloud Management and Automation Advanced Design
Why customers love us?
What do our customers say?
The resources provided for the VMware certification exam were exceptional. The exam dumps and video courses offered clear and concise explanations of each topic. I felt thoroughly prepared for the 5V0-34.19 test and passed with ease.
Studying for the VMware certification exam was a breeze with the comprehensive materials from this site. The detailed study guides and accurate exam dumps helped me understand every concept. I aced the 5V0-34.19 exam on my first try!
I was impressed with the quality of the 5V0-34.19 preparation materials for the VMware certification exam. The video courses were engaging, and the study guides covered all the essential topics. These resources made a significant difference in my study routine and overall performance. I went into the exam feeling confident and well-prepared.
The 5V0-34.19 materials for the VMware certification exam were invaluable. They provided detailed, concise explanations for each topic, helping me grasp the entire syllabus. After studying with these resources, I was able to tackle the final test questions confidently and successfully.
Thanks to the comprehensive study guides and video courses, I aced the 5V0-34.19 exam. The exam dumps were spot on and helped me understand the types of questions to expect. The certification exam was much less intimidating thanks to their excellent prep materials. So, I highly recommend their services for anyone preparing for this certification exam.
Achieving my VMware certification was a seamless experience. The detailed study guide and practice questions ensured I was fully prepared for 5V0-34.19. The customer support was responsive and helpful throughout my journey. Highly recommend their services for anyone preparing for their certification test.
I couldn't be happier with my certification results! The study materials were comprehensive and easy to understand, making my preparation for the 5V0-34.19 stress-free. Using these resources, I was able to pass my exam on the first attempt. They are a must-have for anyone serious about advancing their career.
The practice exams were incredibly helpful in familiarizing me with the actual test format. I felt confident and well-prepared going into my 5V0-34.19 certification exam. The support and guidance provided were top-notch. I couldn't have obtained my VMware certification without these amazing tools!
The materials provided for the 5V0-34.19 were comprehensive and very well-structured. The practice tests were particularly useful in building my confidence and understanding the exam format. After using these materials, I felt well-prepared and was able to solve all the questions on the final test with ease. Passing the certification exam was a huge relief! I feel much more competent in my role. Thank you!
The certification prep was excellent. The content was up-to-date and aligned perfectly with the exam requirements. I appreciated the clear explanations and real-world examples that made complex topics easier to grasp. I passed 5V0-34.19 successfully. It was a game-changer for my career in IT!


