
- Home
- VMware Certifications
- 3V0-42.20 Advanced Design VMware NSX-T Data Center Dumps
Pass VMware 3V0-42.20 Exam in First Attempt Guaranteed!
Get 100% Latest Exam Questions, Accurate & Verified Answers to Pass the Actual Exam!
30 Days Free Updates, Instant Download!


3V0-42.20 Premium File
- Premium File 57 Questions & Answers. Last Update: Nov 10, 2026
Whats Included:
- Latest Questions
- 100% Accurate Answers
- Fast Exam Updates
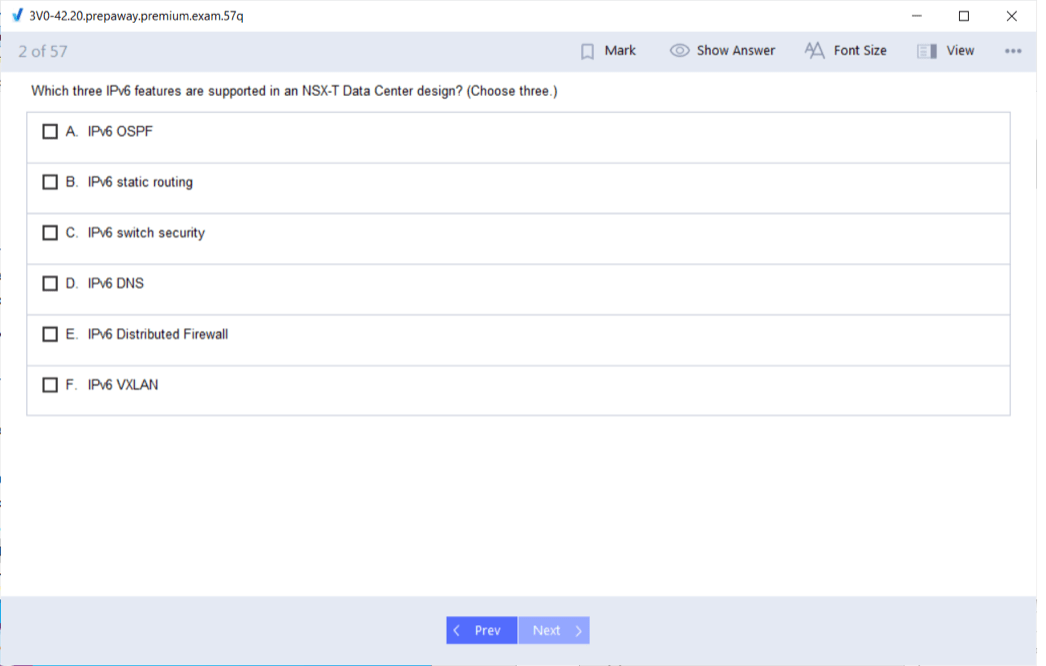
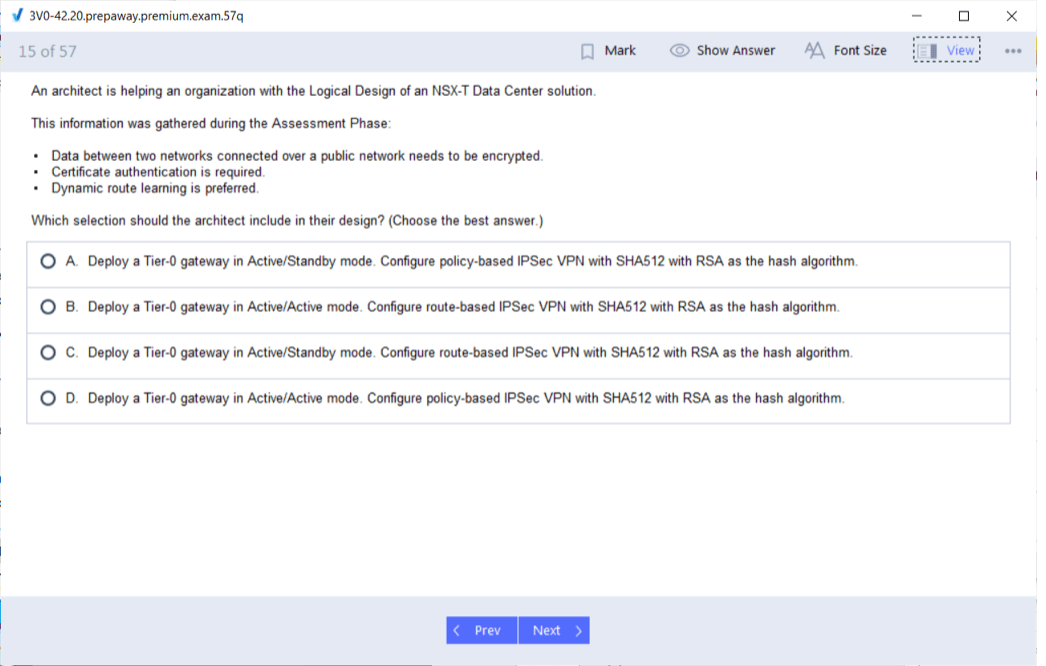
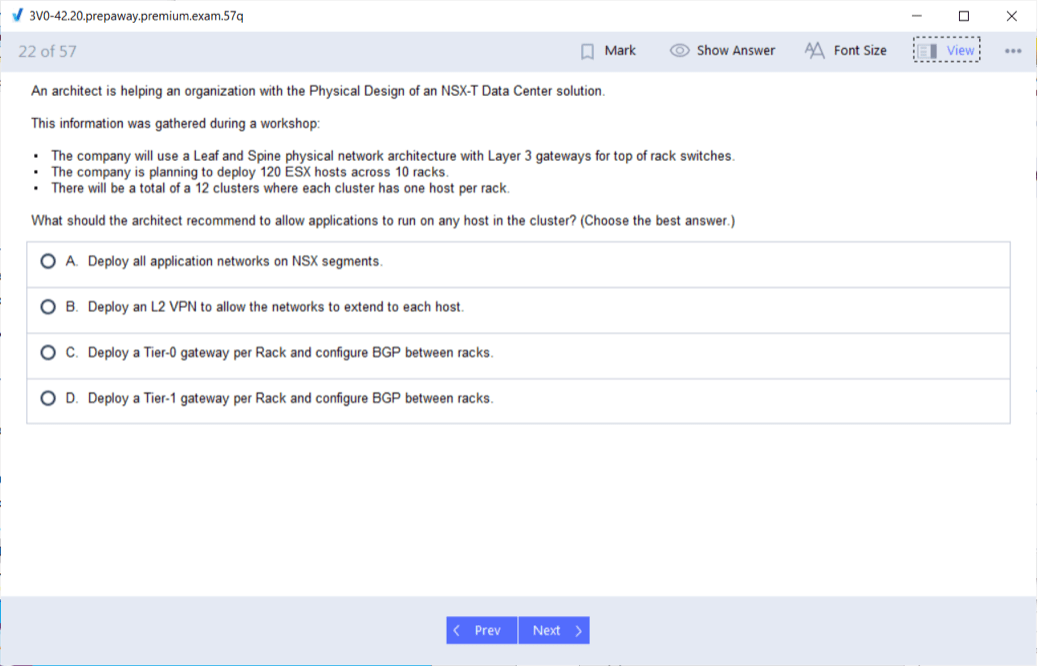
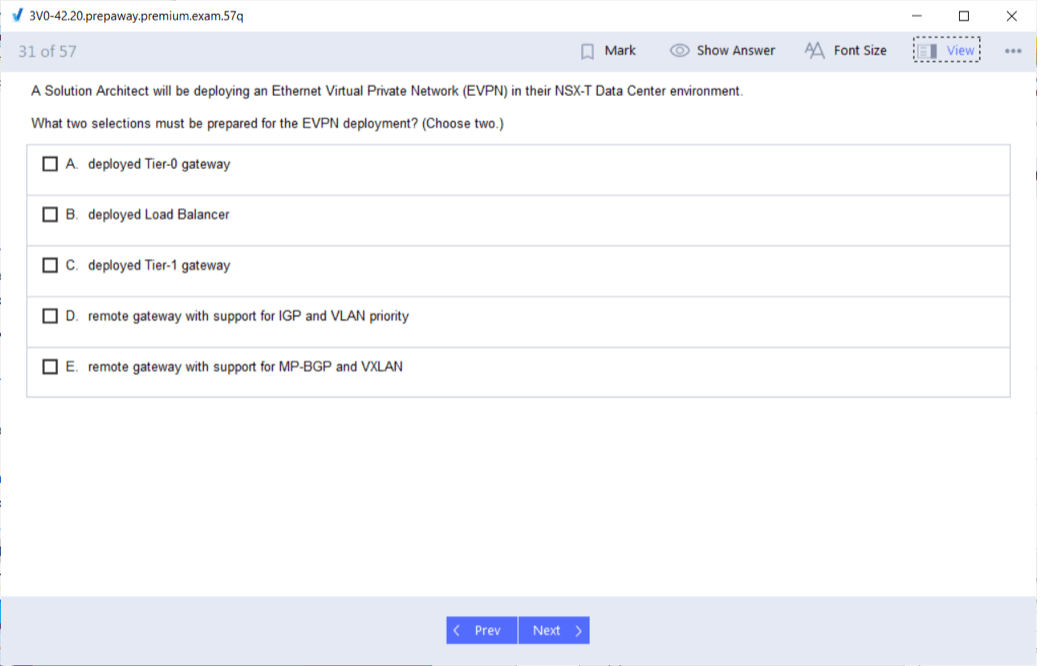
Last Week Results!
 83% students found the test questions almost same
3V0-42.20 Advanced Design VMware NSX-T Data Center 3.0: Designing Networks That Survive Real Constraints
3V0-42.20 was the Advanced Design VMware NSX-T Data Center 3.0 exam used for the VCAP Network Virtualization Design path. Broadcom’s current retirement record lists the exam as retired in March 2025, so it should be treated as a legacy design assessment rather than a current booking target. Its value now is the design method it represents: translating business requirements, risks, assumptions, and constraints into a network-virtualization architecture that can actually be operated.
The exam sits between product knowledge and architecture judgment. A candidate could know how to create segments, gateways, transport zones, edge nodes, and distributed firewall rules yet still produce a weak design if those components were selected without understanding traffic flows, failure behavior, capacity, security boundaries, and operational ownership. Learners moving toward the current VMware Cloud Foundation Networking path will recognize the same architectural habit: technical features matter only after the required outcome is clear.
Preparation is therefore stronger when every topic is framed as a decision. Instead of asking only what an NSX component does, ask why one topology is preferable to another, what dependency it creates, how it behaves during failure, and what evidence would cause the design to change. That reasoning makes an older blueprint useful even after the exam code itself has retired.
Requirements must be separated from preferences before any topology is drawn
A design begins with requirements that can be tested. Availability targets, recovery expectations, supported workload types, regulatory controls, east-west traffic volume, north-south bandwidth, site count, operational staffing, and change windows all constrain the solution. Preferences such as “use active-active everywhere” or “put every service behind the same gateway” should not be accepted until they are tied to an actual requirement.
Classify statements as requirements, constraints, assumptions, and risks. A fixed physical switching platform is a constraint. Expected growth is an assumption until validated. A dependency on one edge cluster may be a risk. A requirement should be measurable enough that another architect can test whether the finished design satisfies it. This discipline prevents diagrams from becoming decoration instead of engineering evidence.
It also exposes trade-offs early. A design optimized for isolation may increase routing complexity. A design optimized for simple operations may accept fewer failure domains. The broader practice of network security through trust boundaries and failure domains is useful here because isolation, resiliency, and manageability are linked decisions rather than independent checkboxes.
The transport design determines what the overlay can reliably promise
NSX-T overlays depend on a physical underlay that provides consistent IP reachability, MTU behavior, redundancy, and failure convergence. A logical network can appear elegant while still failing in production because transport-node interfaces, VLAN placement, routing adjacencies, or physical uplinks were treated as somebody else’s problem. Advanced design work has to model the underlay and overlay together.
Transport zones define which transport nodes can participate in particular logical networks, while tunnel endpoints carry encapsulated traffic across the fabric. The design should show where TEP addresses come from, how they are routed, what happens when an uplink fails, and how MTU is preserved across every physical hop. Oversubscription and asymmetric physical paths matter because overlays do not remove bandwidth limits or latency.
East-west behavior deserves special attention. Modern application tiers often exchange more traffic with one another than with external users, so the physical fabric should avoid unpredictable detours and bottlenecks. The same logic behind predictable east-west paths in data-center fabrics applies to NSX designs: consistent pathing makes capacity planning, troubleshooting, and failure analysis much more defensible.
Tier-0 and Tier-1 gateways encode organizational boundaries as well as routing
Gateway placement is not just a routing exercise. Tier-0 gateways connect the NSX environment to external networks, while Tier-1 gateways create boundaries for applications, tenants, or operational domains. The number of gateways, their high-availability modes, and their relationship to edge clusters affect scale, fault isolation, route control, and the blast radius of change.
Ask where dynamic routing is required and where static behavior is acceptable. Consider route advertisement, summarization, BGP policy, redistribution, ECMP, and failure detection as one system. A route that exists is not automatically a route that should be advertised everywhere. Designs become easier to reason about when routing policy follows ownership and security intent rather than growing organically from convenience.
The older VMware Network Virtualization professional path covers the operational layer beneath these decisions, while the advanced design perspective asks whether the chosen gateway model remains supportable during maintenance, component loss, growth, and cross-site expansion. Both perspectives are necessary in real environments.
Edge capacity must be modeled from services, not from appliance count
Edge nodes can host routing and centralized services such as NAT, load balancing in relevant product versions, VPN functions, and other north-south capabilities. Sizing them by counting appliances is weak because service mix changes CPU, memory, throughput, session, and failure requirements. A design should state expected traffic and service behavior, then map those needs to edge-cluster capacity.
Failure math matters. If an edge cluster can sustain normal load only when every node is healthy, it does not have practical redundancy. Maintenance creates the same requirement as failure: one node may be intentionally unavailable while traffic and services continue. Capacity should therefore be evaluated for degraded states, not just for a perfect-day benchmark.
Placement also influences latency and traffic tromboning. Centralizing every service can simplify management but create long paths between workloads and the functions they consume. The design should explain why centralization or distribution is appropriate for the organization instead of assuming one pattern is universally best.
Micro-segmentation works only when policy follows application intent
The distributed firewall is powerful because enforcement can occur close to workloads, but a large rule base can still become unmanageable if groups, tags, naming, and ownership are inconsistent. Begin with application flows and trust relationships. Identify which systems should communicate, on which ports or services, and under what identity or environment conditions.
Security policy should be designed around stable attributes where possible rather than fragile IP-address lists. Tags and groups can express application tier, environment, sensitivity, or ownership, but only if lifecycle processes keep those attributes accurate. Zero-trust architecture across identity, data, applications, and networks makes the same point: access decisions are stronger when they reflect context instead of assuming that location equals trust.
Policy evaluation should also include logging, exception handling, and rollback. A technically correct deny rule can still cause an outage if dependencies were missed. Good designs provide a path from observed traffic to proposed policy, controlled enforcement, validation, and ongoing cleanup. Security architecture is an operating process, not merely an initial firewall deployment.
North-south security has to reflect real traffic architecture
Perimeter rules, distributed rules, NAT, service insertion, and external firewalls should form a coherent enforcement model. If teams cannot explain where a flow is filtered and which system owns the decision, troubleshooting and audit work become expensive. Avoid duplicating the same policy in several places unless the defense-in-depth benefit is explicit.
The useful question is not “where can we put a firewall?” but “where can we enforce the control with the right context and the least operational ambiguity?” The idea that firewall design starts with traffic architecture fits naturally with NSX because security boundaries should be based on flows, trust levels, and failure consequences.
Design documentation should include external dependencies such as upstream routing, physical firewalls, DNS, load balancers, identity services, and logging platforms. Network virtualization changes where controls can live, but it does not make the surrounding network disappear.
Availability requires explicit failure scenarios rather than generic redundancy
“Highly available” is not a design statement until the failure is named. Model transport-node loss, edge-node loss, uplink failure, top-of-rack switch failure, routing-neighbor loss, management-plane impairment, and site isolation where relevant. For each scenario, identify what continues, what reconverges, what becomes unavailable, and what the operator must do.
Control, management, and data-plane dependencies should be distinguished. A temporary management outage may prevent configuration changes without interrupting existing traffic, while a failed data-plane component can affect packet forwarding immediately. These differences matter during incident response because the visible symptom may not identify the failed plane.
Recovery objectives should also account for human work. A design that technically survives a failure but requires an undocumented sequence of manual actions is less resilient than the diagram suggests. Runbooks, monitoring, tested failover, and clear ownership are part of availability architecture.
Automation is valuable only when the network has a trustworthy source of intent
NSX exposes APIs and supports automated provisioning, but automation magnifies both good and bad design. If naming, addressing, policy structure, and ownership are inconsistent, scripts can reproduce inconsistency faster. Before automating changes, define the data model that describes networks, segments, gateway relationships, security groups, and lifecycle state.
Infrastructure-as-code practices can make intended state reviewable and repeatable. The lesson in infrastructure as code for network teams applies well to virtual networking: version changes, validate them before deployment, make dependencies visible, and ensure the automation can detect drift rather than assuming the environment never changes outside the pipeline.
Operational safety requires staged rollout, prechecks, idempotent behavior where possible, and a recovery path. A design is stronger when it explains which changes can be automated confidently and which high-risk operations still require deliberate approval.
Build a representative scenario with business requirements, two or more application tiers, external connectivity, security constraints, growth expectations, and failure requirements. Produce a logical design, a physical design, and a set of assumptions. Then challenge every choice: why this transport-zone boundary, why this edge placement, why this routing policy, and what happens if the most important assumption becomes false?
Compare design knowledge with deployment behavior by reviewing the older Advanced Deploy VMware NSX-T Data Center 3.x scope. A design decision is more credible when the architect understands how administrators will implement and troubleshoot it. Conversely, an operator becomes a stronger designer when configuration steps are connected to capacity, risk, and lifecycle consequences.
Because 3V0-42.20 is retired, candidates should not prepare as though passing this exact code is the goal. Use the legacy blueprint to sharpen architecture reasoning, then map those skills to current VMware certifications and the VMware Cloud Foundation networking track. The durable outcome is the ability to explain, test, and defend a network design under real constraints.
Why customers love us?
What do our customers say?
The resources provided for the VMware certification exam were exceptional. The exam dumps and video courses offered clear and concise explanations of each topic. I felt thoroughly prepared for the 3V0-42.20 test and passed with ease.
Studying for the VMware certification exam was a breeze with the comprehensive materials from this site. The detailed study guides and accurate exam dumps helped me understand every concept. I aced the 3V0-42.20 exam on my first try!
I was impressed with the quality of the 3V0-42.20 preparation materials for the VMware certification exam. The video courses were engaging, and the study guides covered all the essential topics. These resources made a significant difference in my study routine and overall performance. I went into the exam feeling confident and well-prepared.
The 3V0-42.20 materials for the VMware certification exam were invaluable. They provided detailed, concise explanations for each topic, helping me grasp the entire syllabus. After studying with these resources, I was able to tackle the final test questions confidently and successfully.
Thanks to the comprehensive study guides and video courses, I aced the 3V0-42.20 exam. The exam dumps were spot on and helped me understand the types of questions to expect. The certification exam was much less intimidating thanks to their excellent prep materials. So, I highly recommend their services for anyone preparing for this certification exam.
Achieving my VMware certification was a seamless experience. The detailed study guide and practice questions ensured I was fully prepared for 3V0-42.20. The customer support was responsive and helpful throughout my journey. Highly recommend their services for anyone preparing for their certification test.
I couldn't be happier with my certification results! The study materials were comprehensive and easy to understand, making my preparation for the 3V0-42.20 stress-free. Using these resources, I was able to pass my exam on the first attempt. They are a must-have for anyone serious about advancing their career.
The practice exams were incredibly helpful in familiarizing me with the actual test format. I felt confident and well-prepared going into my 3V0-42.20 certification exam. The support and guidance provided were top-notch. I couldn't have obtained my VMware certification without these amazing tools!
The materials provided for the 3V0-42.20 were comprehensive and very well-structured. The practice tests were particularly useful in building my confidence and understanding the exam format. After using these materials, I felt well-prepared and was able to solve all the questions on the final test with ease. Passing the certification exam was a huge relief! I feel much more competent in my role. Thank you!
The certification prep was excellent. The content was up-to-date and aligned perfectly with the exam requirements. I appreciated the clear explanations and real-world examples that made complex topics easier to grasp. I passed 3V0-42.20 successfully. It was a game-changer for my career in IT!


