Legacy AWS SysOps Exam: How the Operations Track Became SOA-C03 CloudOps
The generic “AWS SysOps†exam name belongs to an older stage of the AWS operations certification track. AWS later standardized the credential as Certified SysOps Administrator – Associate and then renamed the current version AWS Certified CloudOps Engineer – Associate with SOA-C03. New candidates should use the SOA-C03 CloudOps Engineer exam and current AWS documentation rather than trying to schedule an exam under the older SysOps wording.
The transition matters because cloud operations has broadened. The current AWS CloudOps Engineer – Associate certification still covers monitoring, reliability, deployment, security, networking, and troubleshooting, but it reflects modern container platforms, automation, infrastructure as code, multi-account operation, and current AWS service patterns. Legacy SysOps material is valuable when it teaches those durable skills, not when it freezes an old service catalog.
This older page should therefore be treated as a bridge between historical terminology and the current path. The broader set of AWS certifications now separates foundational cloud literacy, architecture, development, data, machine learning, security, operations, and professional DevOps more clearly than early SysOps materials often did.
Operations certification evolved because the job evolved
Early cloud administration looked familiar to traditional systems work: launch instances, configure networks, attach storage, monitor utilization, and back up state. As AWS environments matured, operators became responsible for managed databases, serverless systems, containers, organization-level controls, event-driven automation, and infrastructure expressed as code. The certification name changed because the work was no longer accurately described by a narrow systems-administrator label.
The SysOps Administrator career path remains useful historical context, but the modern CloudOps role expects broader automation and platform awareness. Candidates should think like service owners: define health, reduce manual toil, design recovery, protect access, and make routine changes reproducible.
A CloudOps engineer needs a mental model of every operational signal
Metrics, logs, events, traces, audit records, health checks, and configuration history each answer different questions. If a workload is slow, infrastructure utilization may identify saturation, application logs may show retries, traces may expose a slow downstream dependency, and CloudTrail may reveal a recent configuration change. Effective troubleshooting selects the evidence source that can distinguish among hypotheses.
Centralization is important as environments scale. Teams should be able to investigate across accounts without granting broad direct access to production systems. Log retention, encryption, indexing cost, and access control become part of the design. An operations platform that records everything but cannot correlate it during an incident is not mature observability.
Correlation across signals is what turns observability into troubleshooting. A deployment event may be followed by a latency change, an error burst, and an autoscaling response. Looking at each graph independently can hide the causal sequence. Consistent timestamps, structured fields, trace identifiers, and change records make it easier to reconstruct what happened and decide whether the fix belongs in code, infrastructure, capacity, or policy.
Automation should remove repetitive work without hiding failure
Runbooks are useful when they describe repeatable actions, but automation is better for tasks that are frequent, well understood, and safe to execute under defined conditions. Systems Manager, EventBridge, Lambda, Step Functions, CloudFormation, and other tools can patch systems, remediate configuration, deploy resources, or coordinate response. The best design also records the action and exposes failures clearly.
Automation should not become an unreviewed superuser. Roles need least privilege, inputs need validation, and high-impact actions may require approval. Idempotent operations reduce damage from retries. Rollback or compensation should be considered before automating a destructive change. Modern CloudOps questions reward designs that reduce toil while preserving control and evidence.
Automation also needs lifecycle ownership. Scripts and runbooks should be tested when dependencies or APIs change, and someone should be responsible for failed executions. A remediation that stopped working months ago can create false confidence if the alert still closes automatically. Treat operational automation as production software: version it, observe it, review permissions, and retire workflows that no longer match the environment.
Reliability comes from rehearsed recovery and controlled change
Many outages are triggered by changes rather than hardware failure. Operators should use health checks, staged deployment, maintenance windows, change records, and rollback strategies to limit blast radius. Auto Scaling and load balancing handle some failures automatically, while backups, snapshots, replicas, or cross-Region patterns support data and disaster recovery.
Recovery objectives provide the decision framework. If an application can tolerate hours of downtime and some data loss, a lower-cost backup strategy may be appropriate. If it must continue serving during an Availability Zone failure, redundancy must already be active. The operator should understand which parts can be recreated from templates and which state requires protected copies.
Network troubleshooting starts with the route, then the control
Connectivity problems are easier to solve when examined in order: name resolution, route, gateway or endpoint, network policy, load balancer, target health, and application listener. Security groups are stateful; network ACLs are stateless. Public and private subnets are defined by routing behavior, not by a label. NAT provides outbound translation for private resources but is not a general inbound access mechanism.
Hybrid and multi-account environments add DNS, transit routing, VPN, Direct Connect, and shared inspection. Operators should know where a failure can occur and which logs or metrics can confirm it. The goal is to change the smallest relevant control instead of broadening access until the connection works.
Storage and data operations require lifecycle thinking
Operators manage not only availability of data but also retention, protection, restore, performance, and cost. S3 lifecycle rules can move objects to cheaper classes; EBS snapshots provide block-level backups; databases have managed backup and replication features; file systems require different throughput and sharing considerations. The correct choice follows workload semantics and recovery requirements.
Backup operations should include restore testing, retention verification, and protection from deletion. Cross-account or vault-based isolation may be appropriate for critical data. Encryption keys and permissions must remain available during recovery. A perfectly retained backup is useless if the recovery role cannot decrypt it or the team has never tested the restore sequence.
Capacity alarms should account for different storage behavior. A filesystem approaching fullness is not the same problem as an object bucket growing steadily, and database storage can have performance implications as well as space limits. Operators should understand the metric that actually predicts exhaustion and the expansion mechanism available before setting a generic threshold across every service.
Security is part of daily operations, not a separate audit
CloudOps engineers implement controls that security architecture depends on: patch baselines, IAM roles, security groups, encryption settings, secret rotation, logging, vulnerability findings, and configuration compliance. The work should be standardized and automated where possible so that secure configuration survives team turnover and scale.
Candidates who want deeper security specialization can progress to AWS Security – Specialty. The operational foundation remains valuable because many security incidents are detected and contained through the same monitoring, identity, network, and automation systems used for reliability. Security and operations share the requirement to know what changed and who or what caused it.
CloudOps and DevOps overlap but optimize different parts of the lifecycle
The current operations credential connects naturally with AWS DevOps Engineer – Professional. CloudOps emphasizes deployment, management, reliability, troubleshooting, and security of running workloads. DevOps Professional goes further into software delivery systems, infrastructure automation, resilient application platforms, event response, and governance across the delivery lifecycle.
An operator does not need to become a software engineer to benefit from DevOps practices. Version control, pipelines, immutable artifacts, automated testing, and infrastructure as code make operational work safer. Conversely, DevOps engineers need operational feedback to know whether a release succeeded. The two disciplines meet around automation and observability.
Career progression can also move sideways rather than upward. An operations engineer who spends most of the day on network connectivity may gain more from networking specialization, while someone responsible for security controls may choose the Security Specialty. The current AWS catalog is role-oriented, so the most useful next credential is the one that reflects the systems and decisions you actually own.
Current preparation should deliberately discard obsolete exam assumptions
Legacy SysOps materials may mention service limits, console workflows, exam labs, or feature behavior that no longer matches the current certification. Preserve durable principles—monitoring, recovery, least privilege, capacity, network troubleshooting—and verify implementation details against current AWS documentation. Create a “legacy only†label for notes that cannot be confirmed in SOA-C03.
A practical review can use real-world AWS operations skills to test whether each topic still matters outside the exam. If a concept helps you detect failure, recover service, automate change, protect access, or control cost, it is probably durable. If it exists only because an old course said it was frequently tested, verify it before spending preparation time.
Finally, verify the logistics themselves. Old SysOps material may refer to retired exam codes, lab components, scoring behavior, or registration names. Current candidates should confirm the live exam guide, language availability, testing options, and certification name directly before scheduling. Separating logistics from technical knowledge prevents a correct operations study plan from being attached to the wrong exam version.
Version discipline is part of good cloud practice too: know which documentation describes the system you are actually operating.



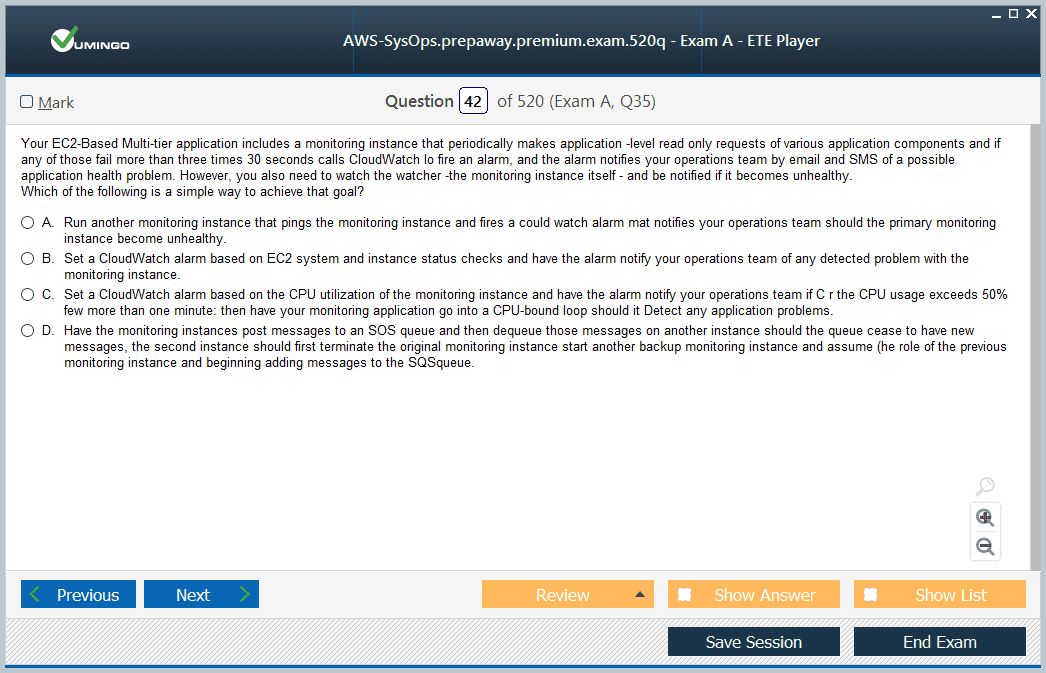
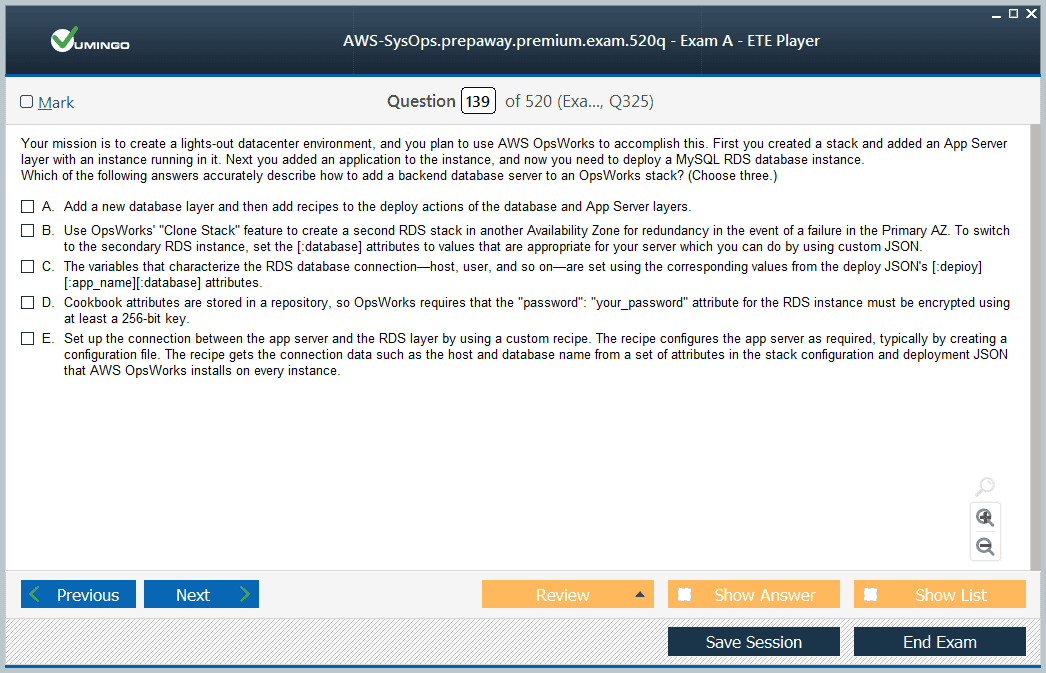
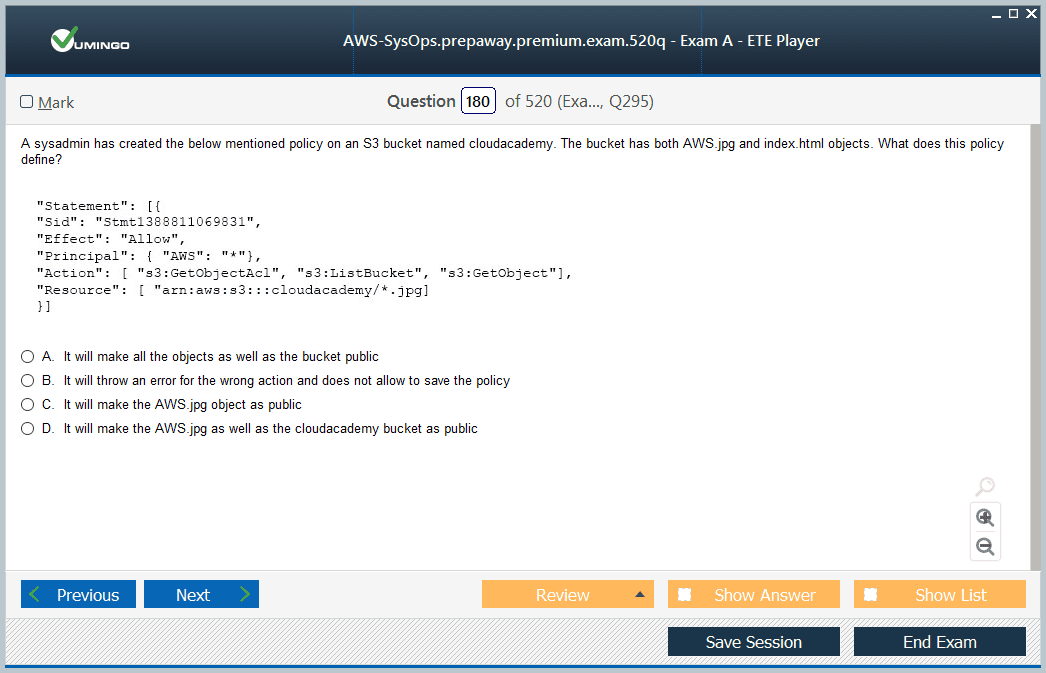
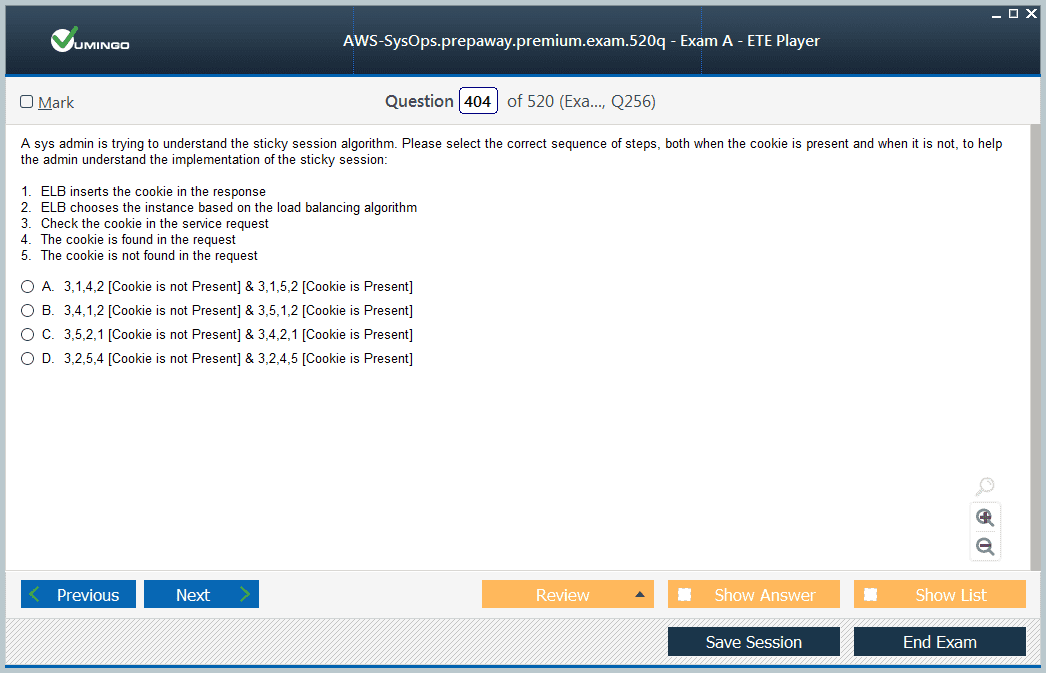




 83% students found the test questions almost same





