F5 101 Application Delivery Fundamentals: Retired Exam and Current BIG-IP Path
F5 exam 101, Application Delivery Fundamentals, was the traditional entry point into the F5 Certified Administrator, BIG-IP path. It tested networking, application-delivery, security, and troubleshooting foundations before candidates moved to exam 201. F5 retired the 101 exam on April 30, 2025, so it cannot be scheduled now.
The current F5 certifications framework for BIG-IP Administrator uses five shorter exams rather than the former 101-plus-201 sequence. The pathway includes F5CAB1, Data Plane Concepts (F5CAB2), F5CAB3, F5CAB4, and F5CAB5.
Old 101 material still has educational value because BIG-IP administration rests on TCP/IP, application protocols, load balancing, security, high availability, and diagnostic reasoning. The correct approach is to preserve those foundations while switching exam preparation to the current blueprint.
The 101 retirement changed the administrator entry path
Under the old model, candidates passed 101 and then 201 TMOS Administration to earn F5 Certified Administrator, BIG-IP. F5 changed the program effective May 1, 2025. Exam 101 was retired and the administrator credential moved to five focused exams that can be taken in any order. This is a structural change, not merely a renamed exam.
That distinction affects study material. A 101 course can strengthen fundamentals, but it cannot represent the current booking path or complete the new certification requirements. Candidates should use current F5 blueprints for exam scope and use legacy resources only when they explain concepts that remain relevant.
Application delivery begins with understanding client-server traffic
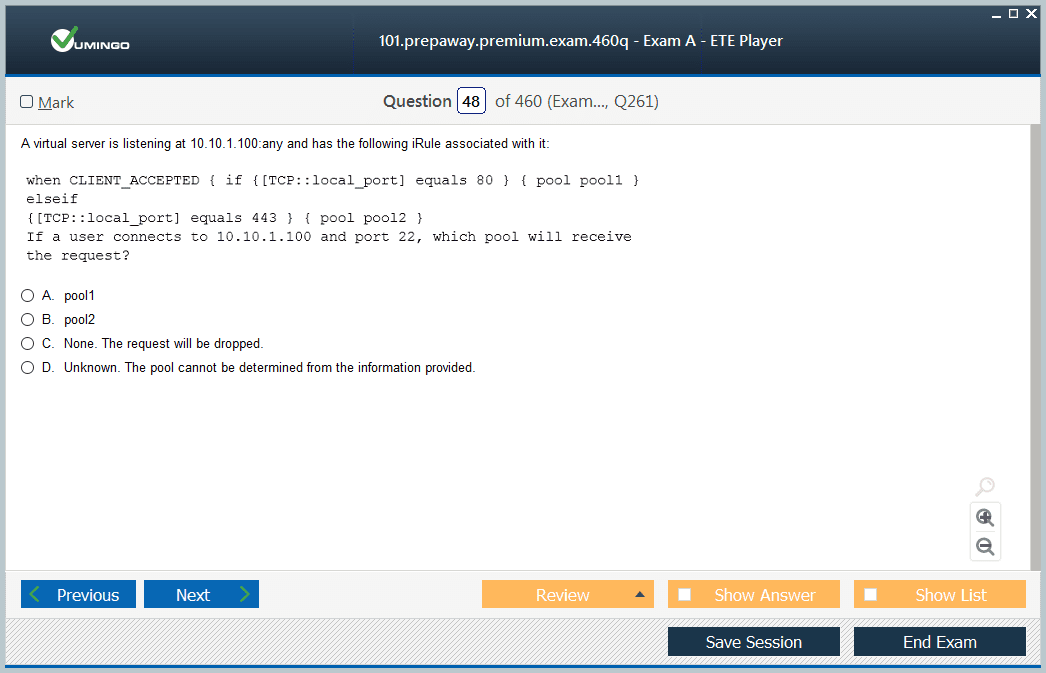
BIG-IP sits in the path between clients and application resources, so administrators must reason about source and destination addresses, ports, protocols, connections, and return paths. A virtual server receives traffic according to configured criteria and can direct it toward pools of backend resources. If the networking model is unclear, higher-level configuration becomes guesswork.
Review subnetting, gateways, ARP or neighbor discovery, routing, TCP state, UDP behavior, and common service ports. The IPv4 subnetting foundation is particularly useful because address and route mistakes can make a healthy application appear unavailable.
DNS belongs in that traffic model even though it may sit outside the BIG-IP configuration being studied. Clients often reach applications through names, and DNS can direct them to different addresses, regions, or services. A healthy virtual server does not help a client that resolves the wrong address. In troubleshooting labs, confirm name resolution separately from TCP reachability and application behavior so one successful layer is not mistaken for end-to-end health.
The OSI model is useful when it guides troubleshooting
F5 historically expected 101 candidates to understand the OSI model, but the operational value is more important than memorizing seven labels. Layers provide a way to scope evidence. If a physical link is down, application settings are irrelevant. If TCP handshakes complete but an HTTP request fails, the investigation should move higher in the stack.
Practice describing symptoms in protocol terms. A timeout, reset, TLS alert, HTTP status, DNS failure, or routing drop points to different hypotheses. This layered reasoning remains useful on the current F5CAB exams because administrators still have to decide where traffic stops and which component owns the failure.
Use tools at the layer where they answer the question. Interface counters can reveal physical or data-link errors, route tables expose network-layer decisions, connection tables and captures show transport behavior, and HTTP or TLS tools expose application-layer exchanges. The model becomes practical when it helps select evidence rather than when it is recited as an acronym.
Also learn to distinguish control-plane health from data-plane health. A BIG-IP device can be reachable through its management interface while application traffic is failing, or application traffic can continue while an administrative service has a problem. Checking the right plane prevents false conclusions about overall device status.
Load balancing combines health, policy, and application behavior
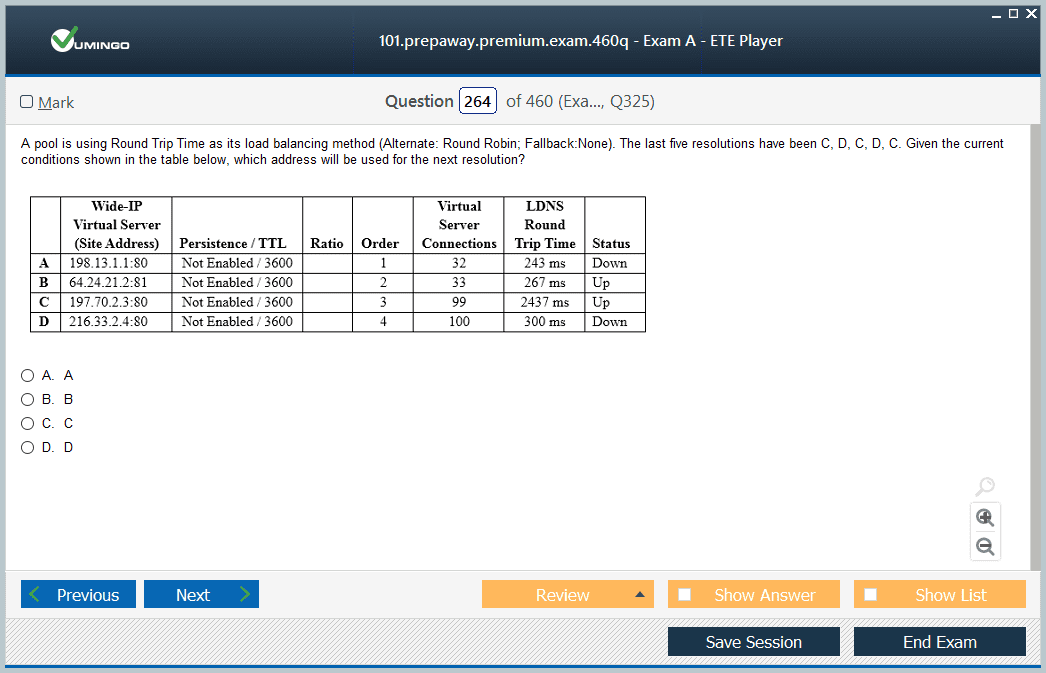
Load balancing is not simply round-robin distribution. A useful configuration accounts for server health, persistence requirements, connection characteristics, application state, capacity, and failure behavior. Pool members should receive traffic only when they can provide the intended service, which makes monitoring a key part of application delivery.
Learn to distinguish a node from a pool member, understand why a monitor can mark a resource unavailable, and consider how persistence affects distribution. These concepts become more advanced in 301b BIG-IP LTM Maintain and Troubleshoot, but the foundation begins with recognizing that the traffic-management decision must reflect application requirements.
The difference between availability and readiness is important. A server can respond to a basic connection while an application dependency such as a database, authentication service, or downstream API is failing. Better health checks target the service outcome that matters without becoming so complex that normal response variation produces false failures. This balance between shallow and deep monitoring remains a core application-delivery judgment.
NAT, SNAT, and routing determine whether return traffic works
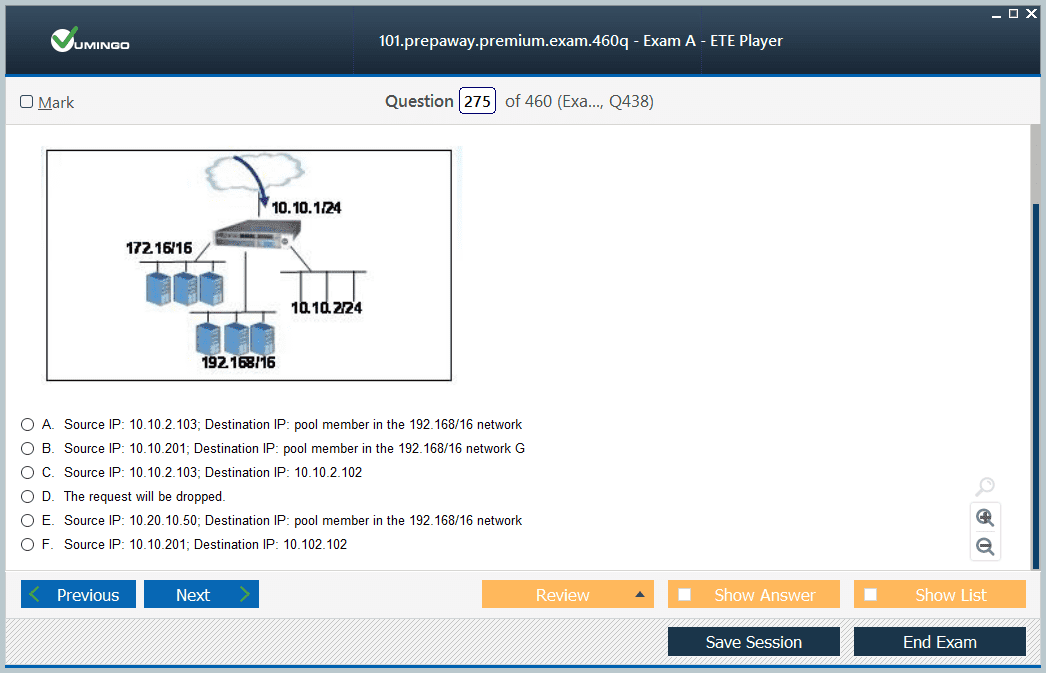
One of the most common application-delivery mistakes is focusing only on the client-to-server path. The server's return traffic must traverse a path that preserves the intended connection state. Source address translation can make BIG-IP the apparent client from the server's perspective, which can solve routing asymmetry but also changes logging and capacity considerations.
Draw both directions for every lab. Mark client, BIG-IP, server, gateways, translated addresses, and routing decisions. A configuration that looks correct on the inbound side can still fail when the server sends responses elsewhere. This habit is more valuable than memorizing isolated NAT terminology.
TLS and HTTP awareness connects infrastructure to applications
Application delivery administrators need enough HTTP knowledge to understand requests, responses, headers, status codes, persistence clues, redirects, and virtual hosting. TLS adds certificates, trust, encryption, protocol negotiation, and client-versus-server side decisions. These are application-layer concerns with direct infrastructure consequences.
Security study should include why encryption protects confidentiality and integrity in transit, how certificate problems present to clients, and where inspection or termination changes trust boundaries. The goal is not to become a cryptographer; it is to reason correctly about what BIG-IP is doing to encrypted application traffic.
HTTP troubleshooting should include host headers, redirects, cookies, caching behavior, and response codes. A 301 redirect loop, a 503 generated by a proxy, and a backend 500 error point to different problems even though users may describe all three as “the site is down.†Being able to read a simple request and response exchange dramatically improves the quality of BIG-IP diagnosis and communication with application teams.
High availability is about preserving service, not just duplicating appliances
A redundant pair needs synchronized configuration, healthy failover communication, compatible software and provisioning, and network designs that allow traffic to move when device state changes. An HA diagram therefore represents relationships and operational procedures, not merely two boxes side by side.
Current F5 exams split these responsibilities across focused objectives, including control-plane management in F5CAB4 and support/troubleshooting in F5CAB5. When using old 101 notes, update them with the current exam structure so availability concepts are studied at the depth now expected.
Operational readiness also includes maintenance. Before an upgrade or failover test, confirm backups, synchronization state, peer health, expected traffic-group ownership, upstream reachability, and rollback options. After the change, validate application service from a client perspective rather than relying only on device status. This converts HA from a diagram feature into a tested service capability.
Troubleshooting should follow traffic and evidence
Good diagnosis starts with a precise problem statement: which application, which clients, which time window, and what changed. Then check device health, interfaces, routing, virtual server status, pool and member state, monitor results, statistics, logs, and captures as needed. The common network troubleshooting patterns can reinforce a systematic approach.
F5 environments make layered troubleshooting especially important because an apparent server failure may originate in health monitoring, persistence, address translation, TLS, routing, or policy. Change one variable at a time and preserve evidence before modifying production configuration.
Observability should include counters before and after a test. If a request is sent but the virtual server connection count does not change, investigate addressing, routing, or listener matching before inspecting backend application logs. If the virtual server receives traffic but no pool member is selected, focus on pool state, policy, or configuration. Each statistic narrows the path and prevents expensive guesswork.
Communication is part of diagnosis. Record the client address, destination, timestamp, expected behavior, actual result, and any correlation identifier the application provides. This lets network, security, and application teams examine the same event rather than comparing unrelated tests performed at different times.
Prepare for the current CAB exams instead of recreating 101
If your goal is a new F5 Certified Administrator credential, build a study matrix around all five current administrator exams. Use F5CAB1 for installation and initial configuration, F5CAB2 for data-plane concepts, F5CAB3 for data-plane configuration, F5CAB4 for control-plane administration, and F5CAB5 for support and troubleshooting. The five exams are deliberately narrower than the old 101/201 pair.
Legacy 101 study is best used as a pre-study foundation. Once networking and application-delivery concepts are comfortable, switch to the current F5 blueprint, current labs, and current exam delivery information. That keeps the durable technical knowledge while avoiding a certification plan based on an exam that F5 has explicitly retired.
A practical sequence is to build one reusable lab and revisit it across the CAB objectives. Install and license the system, configure management access, create basic application objects, add profiles and monitors, form an HA pair, generate traffic, break selected components, and recover them. The same environment can teach installation, data-plane configuration, control-plane administration, and troubleshooting while keeping the relationships between topics visible.
Use the official current blueprint as the final authority for what is assessed. Legacy 101 notes are most useful when they explain durable networking and application-delivery ideas, not when they preserve old exam administration or sequencing that no longer applies.











 83% students found the test questions almost same





